Setting Up Affordable Backconnect Nodes for 2026

Duplicates increase. Values normalize incorrectly. Protection drops in particular regions. Edge cases begin dominating the dataset. Without quality checks, this appears like typical variation. With quality checks, it looks like an early warning. Infrastructure permits you to specify expectations and keep an eye on deviations. Scripts generally simply gather whatever returns. At scale, scraping raises questions beyond engineering.
This becomes particularly crucial when scraped data feeds AI systems. When information affects models, traceability matters. Could you please let me know which source stopped working, when it stopped working, and how much information is affected?
Observability is not an additional function. It is the structure of trust at scale. The majority of groups do not avoid facilities due to the fact that they are careless. They avoid it because scripts feel quicker. Facilities feels heavy and sluggish at the start. This tradeoff is momentary. Every faster way taken early appears later on as rework, firefighting, and loss of confidence.
Best Practices for Maintaining Cost-Efficient Scraping Gateways
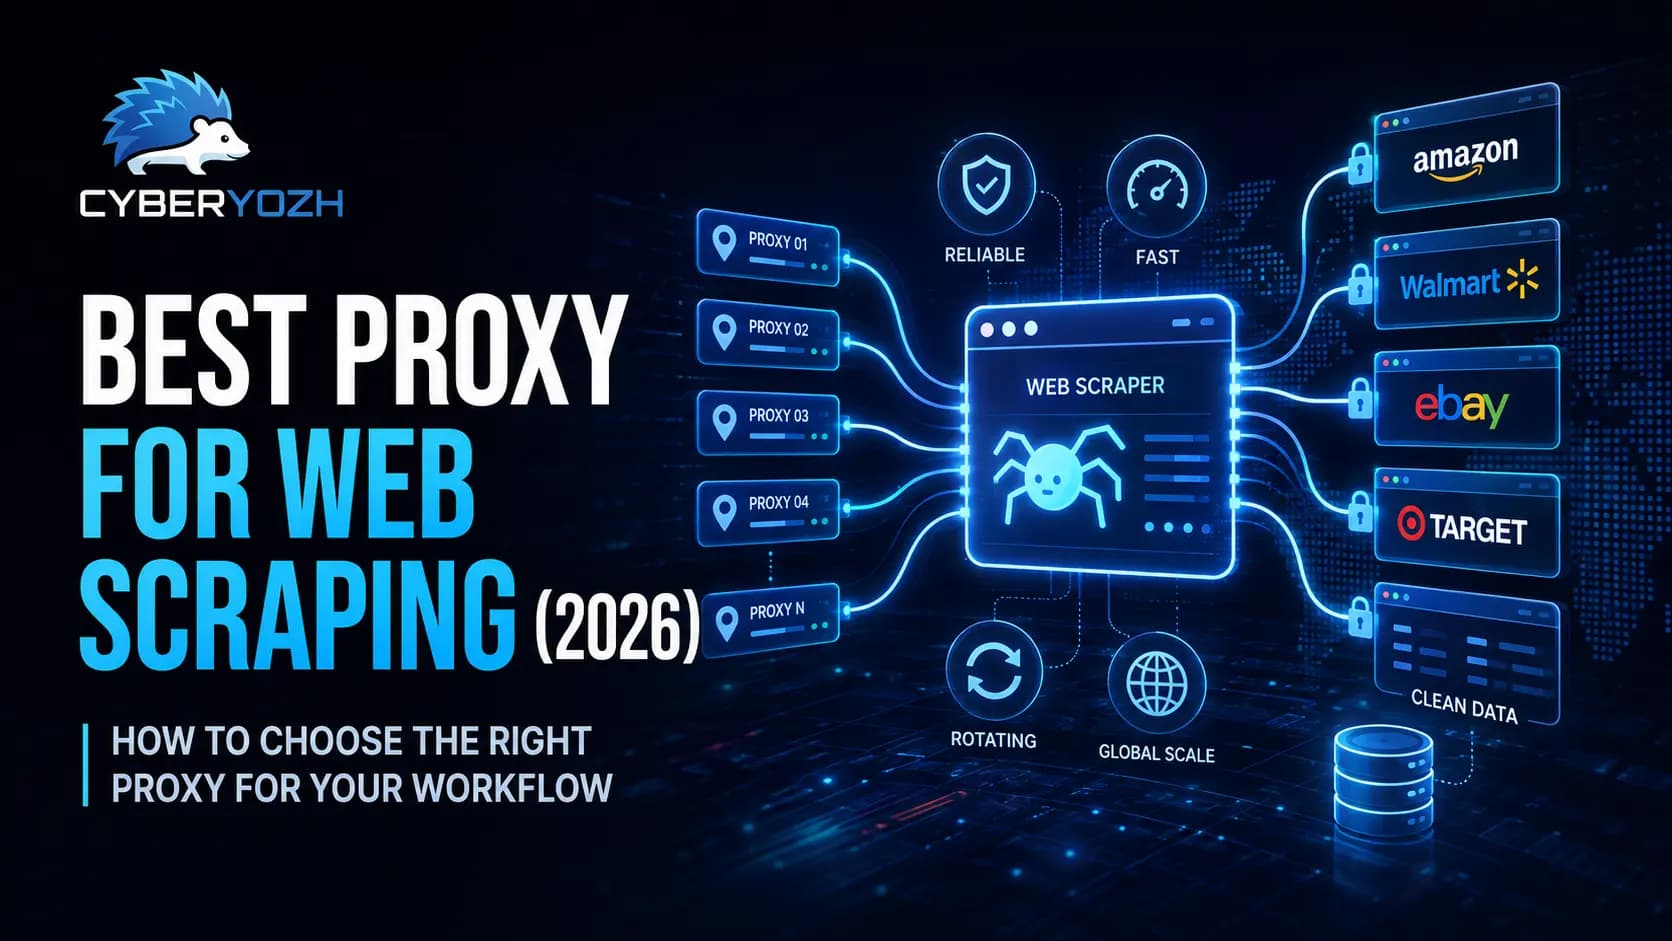
At scale, scraping infrastructure normally consists of central scheduling, source-aware crawling, rate and habits control, proxy and identity management, recognition layers, monitoring, informing, lineage tracking, and healing workflows. Scripts still exist inside this setup.
Web scraping is no longer a side job. When scraping fails, genuine choices are impacted. As the value of web data boosts, so does the cost of getting it incorrect.
It has to do with developing systems that make it through modification. Scripts can begin the journey. Facilities is what makes it dependable. Teams that comprehend this early construct data pipelines they can rely on. Teams that do not normally learn it later, when the cost is much greater. Cheers, guys, see you next time.
Web scraping facilities has replaced manual scripts as the structure of scalable big data operations. Services that as soon as counted on basic page parsers now require full systems that extract, structure, and deliver data in real timeacross locations, platforms, and compliance borders. Tradition scraping toolslike standard spiders and static selectorsfail under pressure.
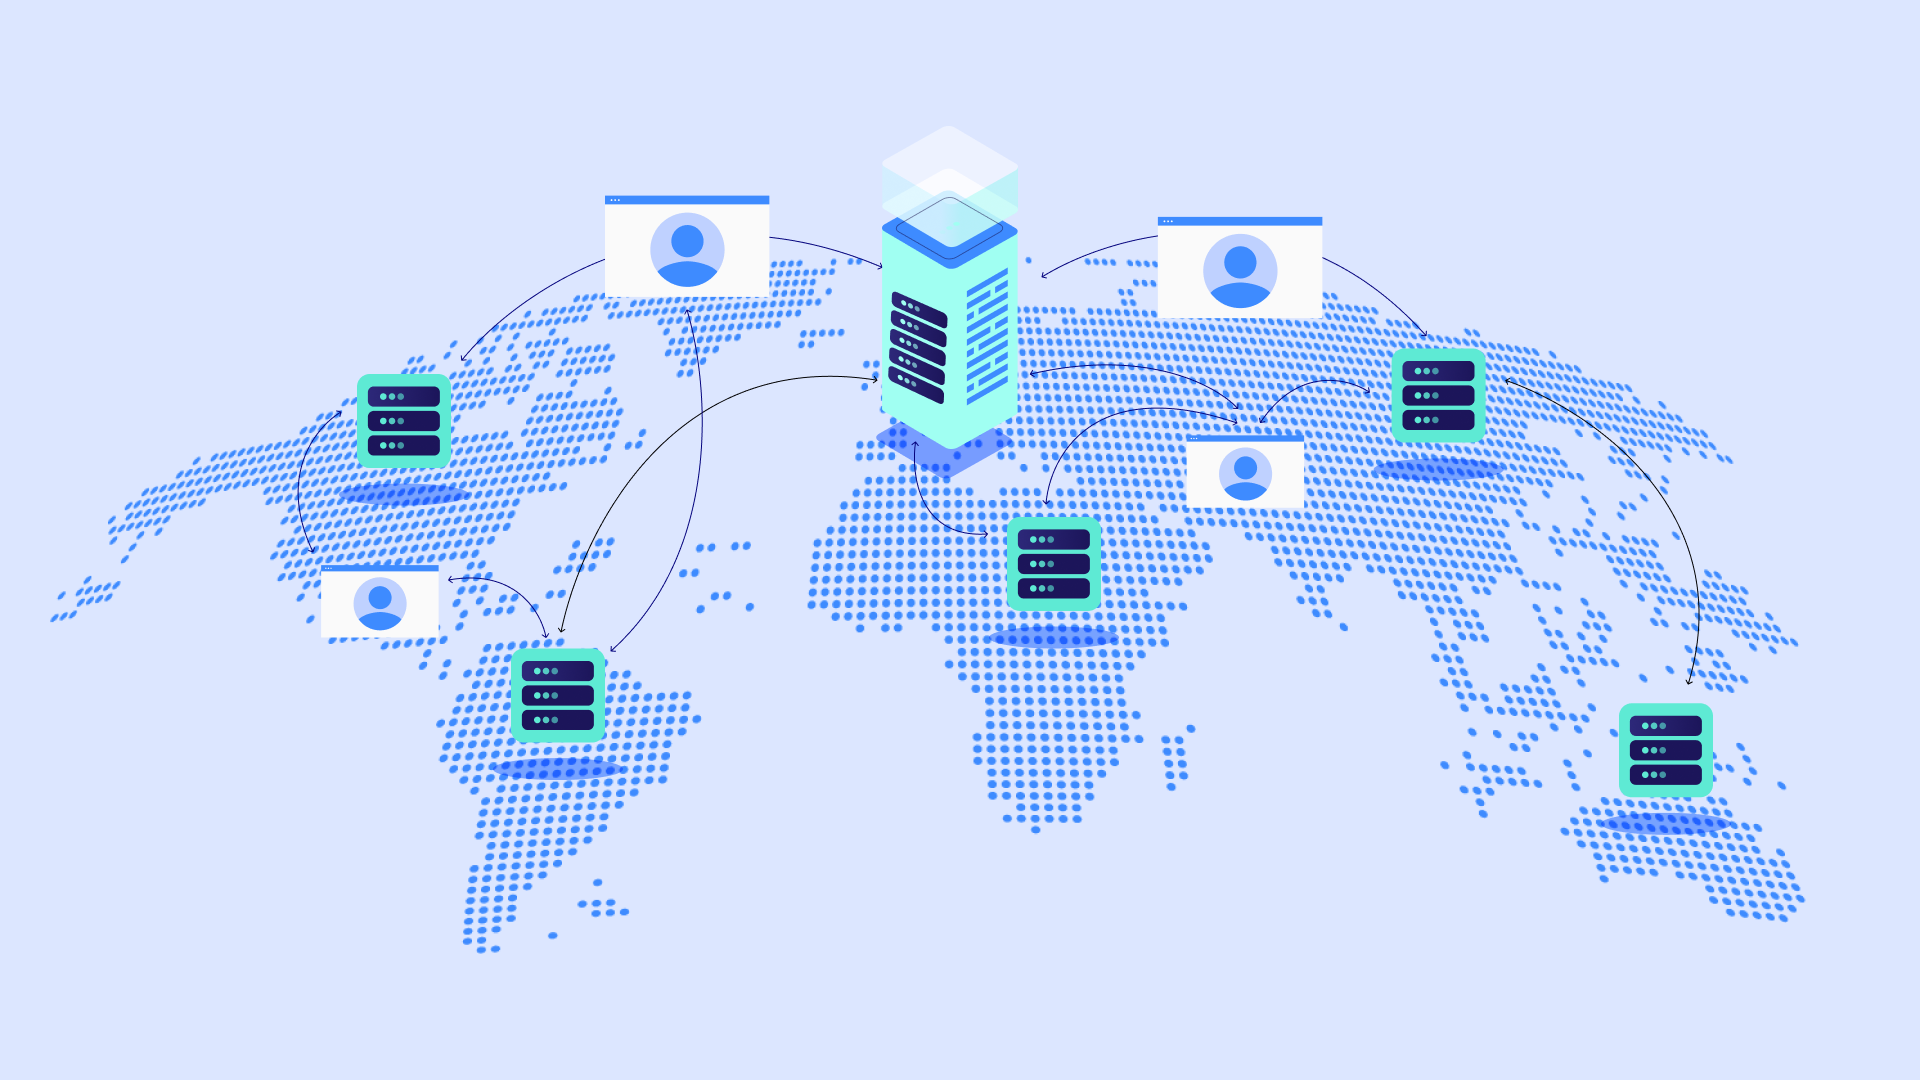
Most significantly, they can't satisfy enterprise requirements: No fault tolerance No schema enforcement No shipment guarantees Distributed web scraping systems are developed for scale. They divided the scraping pipeline into clear layerscrawling, queuing, changing, and deliveringand scale every one individually. These systems adapt dynamically: If a node fails, traffic reroutes.
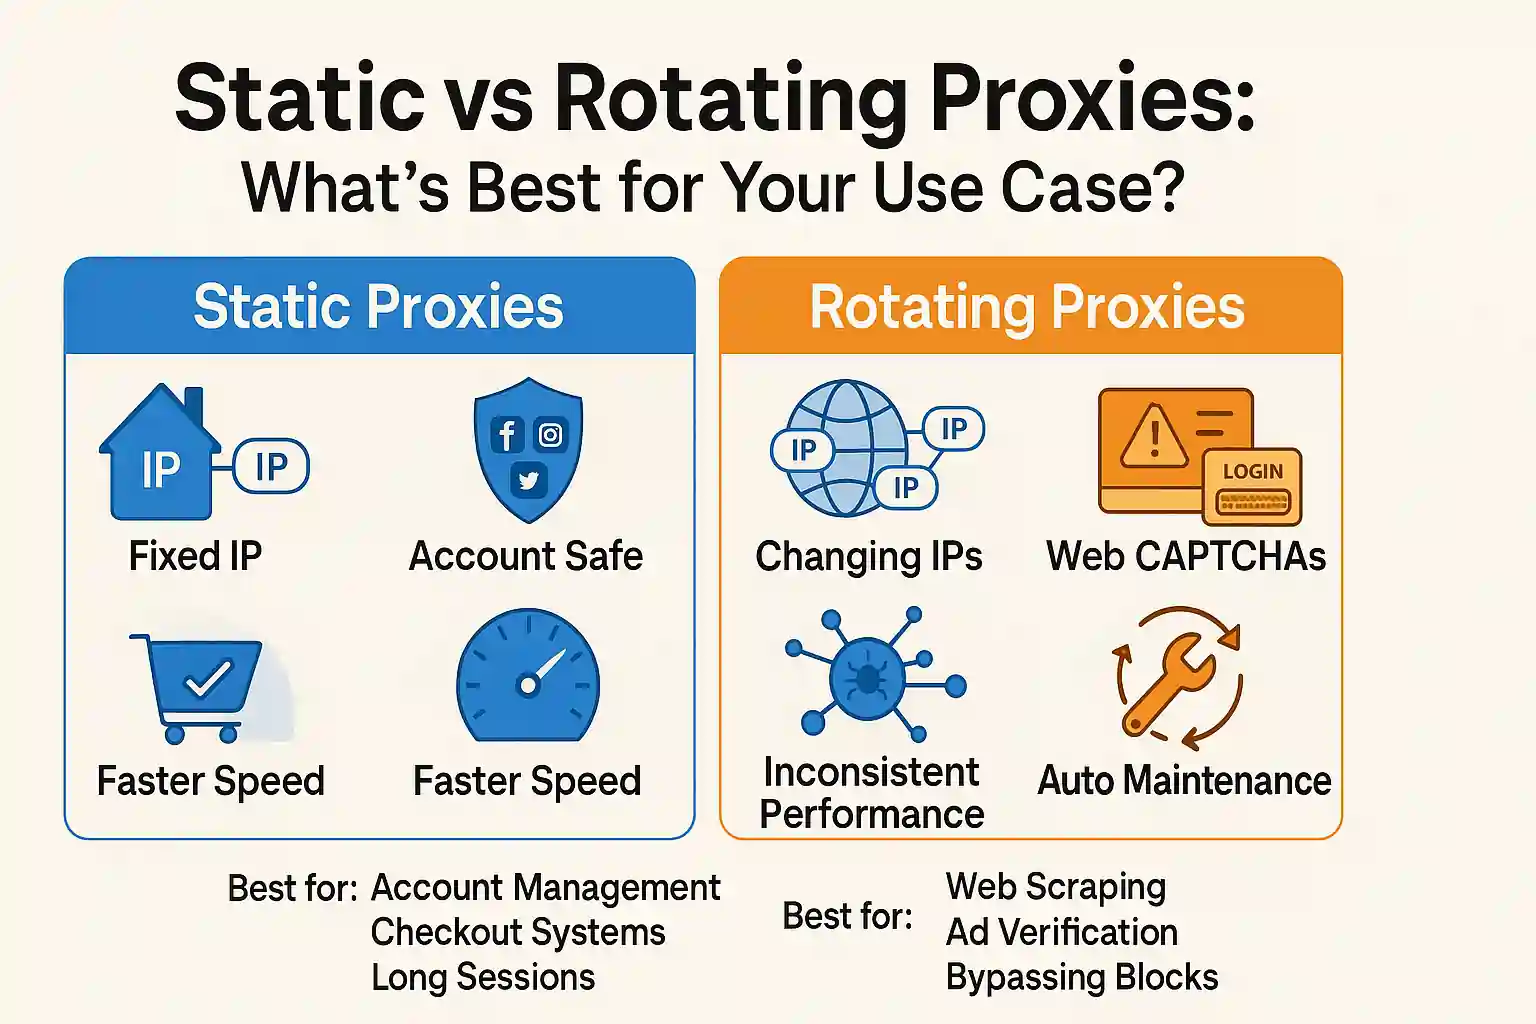
private proxies for SEOImpacts of Rotating Proxy Setups for Businesses
If APIs obstruct, proxies rotate. Governance, observability, and flexible scaling are baked into the architecture, not bolted on after the truth. The outcome is durability. Modern scraping infrastructure does not simply runit recuperates, preserves schema, implements access controls, and incorporates cleanly into downstream systems. This is the distinction between break-fix scripts and production-grade infrastructure.
Market information proves the pattern. Many development forecasts track scraping software. Lots of tools stop working to reflect the hidden invest on internal facilities or outsourced information pipelines.
private proxies for SEO
This focus on durability has led numerous companies to transition from internal scripts to managed services, seeing the procedure as a trusted instance of web scraping as a service. Scraping has moved from the developer desk to the conference room. Companies now see it as an information supply chainsomething that should be observable, repeatable, and compliant.
Modern web data scraping infrastructure is layered by design. Each layer manages a specific functioningestion, change, governance, or deliveryand should scale separately. What follows is a useful blueprint of how dispersed scraping architectures ought to be built for strength, reuse, and real-time operations. Without this modular structure, the infrastructure of scraping systems stops working under pressure.
They produce crawl traffic jams, drop jobs under load, and stop working throughout time zones or areas. Dispersed crawling uses message lines (e.g., Redis, RabbitMQ) and parallel employees to split crawl tasks throughout nodes: Jobs are assigned by concern Failures are retried instantly Regions and load are balanced dynamically Scraping ends up being flexible and fault-tolerant.