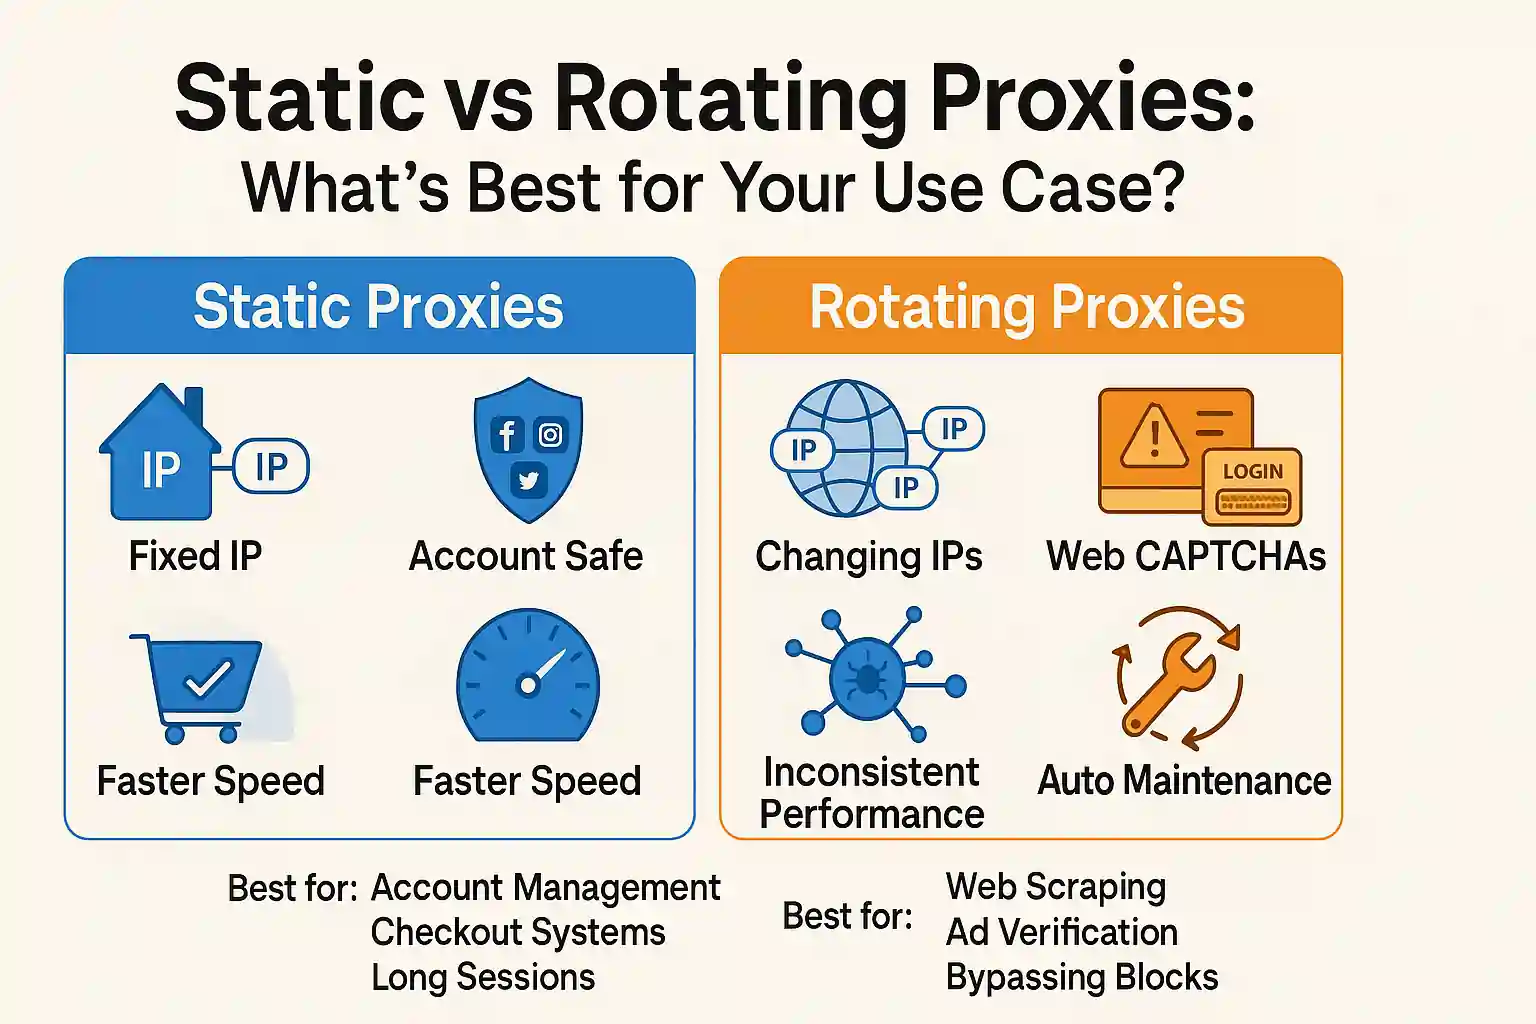
Tuning Rotating Proxy Infrastructure for Speed
Every team that began with a "quick anonymization script" 3 years back now has a 2,000-line Python monolith that no one wishes to touch. The 5 tools below represent various architectural approaches about where anonymization belongs in your stack: at the infrastructure layer, inside the database, or as a pipeline action between environments.
proxy serviceInstead of running a tool against your database, the database platform itself handles masking when you develop branches. The architecture separates calculate (vanilla PostgreSQL) from storage (distributed block storage). Branch creation is a metadata-only operation. Xata copies the index pointing to data chunks, not the chunks themselves. This means branch creation is immediate despite database size.
Just data that diverges after branching takes in extra storage. The anonymization workflow has two phases. xata clone usages pgstream (Xata's open-source CDC tool) to reproduce from any external Postgres, RDS, Aurora, or Cloud SQL into a Xata staging replica. Column-level changes take place throughout replication. Second, designers produce instant copy-on-write branches (CoW: a storage method that shares data blocks in between copies until modifications are made, then only shops the distinctions) from that pre-anonymized reproduction.
proxy service