Scaling Anonymized Data Mining with Advanced Tools
Tokenization is generally utilized to protect payment details or highly delicate information like health records. Tokenization is typically the favored technique in payment processing systems where you need to protect data such as charge card numbers. Because tokenization does not alter the data format, it can be used flawlessly in environments where the information needs to be processed or referenced.
proxy serviceIn this case, credit card numbers are changed with tokens, protecting the actual data while permitting payment systems to operate without exposing sensitive details. Payment processors and e-commerce business dealing with monetary information. Health care companies handling patient health records A pseudonymization tool replaces sensitive information with pseudonyms or identifiers, which can be re-linked to the original information if required.
Pseudonymization is frequently used in health care, research, or legal environments where it is needed to maintain data links without exposing delicate information. It strikes a balance between information personal privacy and functionality. A pharmaceutical company carries out scientific trials and utilizes pseudonymization to change patient names with IDs. If follow-up research study is required, licensed users can trace back the data to the original participants.
This is common in document handling, where sensitive fields such as names, addresses, or account numbers need to be hidden but the general document context is maintained. Redaction is perfect for reports, documents, or files where sensitive details is irrelevant to the reader but other parts of the content need to stay intact.
Cheap Home-Based Proxy Options for 2026
A legal group redacts secret information (such as names or personal identifiers) from a report before sending it for public review. This guarantees personal privacy while enabling the document to be shared. A Perturbation tool presents noise into data, a little altering the values to ensure privacy. While this keeps the usefulness of the data for analysis, it obscures individual-level information, making it tough to reverse-engineer the original details.
proxy serviceThis is perfect for industries that require anonymized datasets for artificial intelligence or huge information analytics. For if you need to anonymize data without jeopardizing accuracy, can attain the same goal without adding noise. A federal government company requires to share anonymized health statistics with scientists. By utilizing perturbation, they can add sound to individual records, ensuring that scientists see the patterns without exposing delicate individual details.
This ensures that the analytical homes of the dataset stay undamaged, however private data points lose their original associations. Information shuffling works when the goal is to secure delicate information for research or analytics while protecting the overall trends or patterns in the dataset. It's typically used in large-scale information analysis where precise data relationships are less crucial.
Future-Proofing Your Anonymized Data Mining Workflow in 2026
The general circulation stays accurate, however no individual deal can be traced back to a particular consumer. Selecting the right data anonymization tool requires comprehending your industry's requirements, your data environment, and the compliance requirements you deal with. Each anonymization technique has its strengths, and your decision needs to show your company's unique requirements.
For environments that demand the greatest security, tokenization and encryption supply robust protection however need more complicated execution. Generalization and pseudonymization are great options for broad analyses and research study, though they might compromise some data precision. Information shuffling is ideal for massive analytics where preserving statistical patterns matters more than maintaining specific record consistency.
That said, every company's requirements are different, and the very best solution depends on your use case. The key is to pick the tool that finest fits your functional requirements while guaranteeing compliance and data security. Although all the above techniques serve important roles, fixed information masking is often the favored option in regulated markets with intricate information environments.
Static data masking allows sensitive information to be anonymized while still maintaining full performance, making it vital for advancement, screening, and analytics environments. By automating the masking process, tools like ADM assistance business satisfy strict GDPR, HIPAA, and PCI-DSS compliance requirements without compromising data structure or integrity.
TABLE OF CONTENT Data anonymization tools can be your best pals or your information quality's worst opponents. Often both. Anonymizing data is never easy, and it gets harder when: You attempt to do your finest and use information anonymization tools daily. You have actually removed all delicate details, masked the rest, and randomized for good measure.
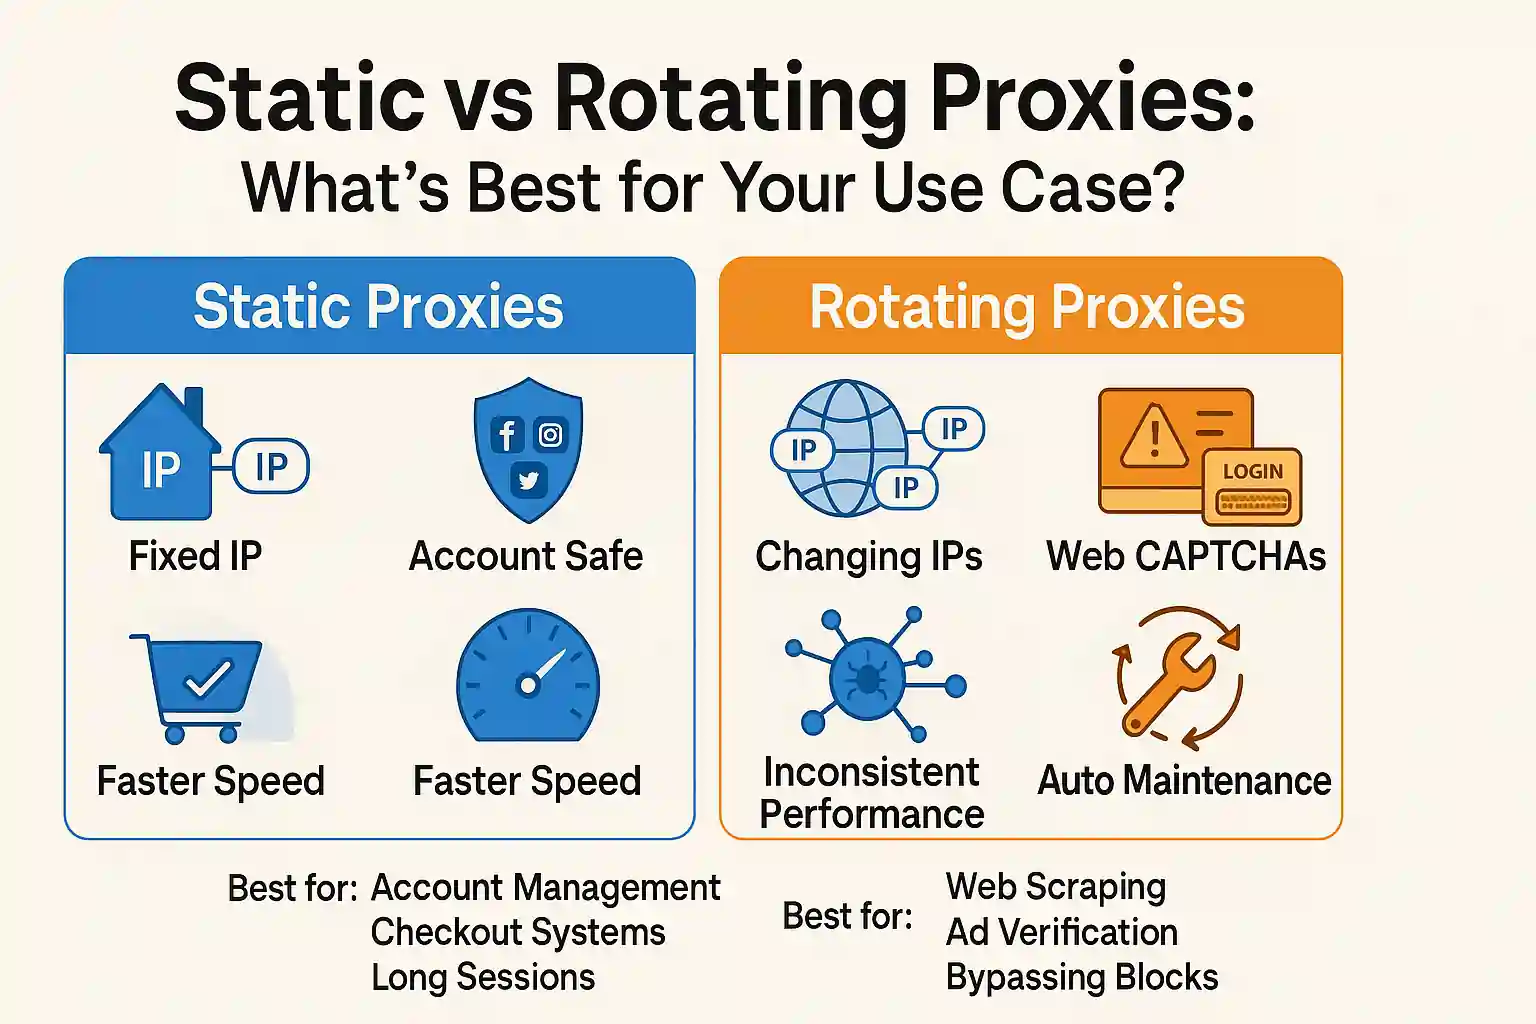
Rotating Proxy Models versus Standard Solutions
Why do so many data anonymization efforts end up being Schmh? Data anonymization tools easily automate the process of information anonymization with the objective of making sure that no private consisted of in the data can be re-identified. The most ancient of information anonymization tools, namely aggregation and the now outdated rounding, were born in the 1950s.