Robust Crawling Workflows for Global Web Projects

A logistics tech company needed to gather path pricing and service times from 50+ freight platforms in near genuine time. The tradition system couldn't manage schedule shifts or dynamic ZIP-based quotes.
A property investment platform needed zoning approvals, permits, and live listings across 300+ city, local, and national sites. We released a system with: Layered crawlers targeting computer system registry, listings, and zoning departments Field-based mapping for address, unit type, and allow phase Information validation against historical maps and tax records Now, acquisition groups get structured updates daily, with listing-to-market lag minimized by 67%.
Each system above was customized utilizing a dispersed web scraping, optimized for the scale, compliance, and lifecycle needs of its market. While their sources and goals differ, the foundation is the very same: Clean input.
Sophisticated Private Data Harvesting Tools and Systems
Even the best-designed scraping systems deal with external volatilityanti-bot escalations, structural page shifts, rate limits, and unforeseeable latency throughout areas. The difficulty isn't just gathering data.
In business deployments, 3 patterns appear frequently: Page structures move daily, particularly on vibrant retail, booking, and financing platforms. Fixed XPaths or CSS selectors end up being invalid silently. Without vibrant queuing, retry storms overload systems. Rather of an elegant healing, pipelines crash under duplicated failure. What's legal to extract in one region may be limited in another.
To counter this, the facilities of data scraping need to develop beyond scripts and ad-hoc retries. We engineer scraping systems to perform under production-grade constraints: Task circulations are decoupled and priority-driven, permitting quick rerouting under load.
Advantages of Automatic Proxy Infrastructures for Teams
This web scraping facilities doesn't just fix what's brokenit prevents quiet decay. When a scraper fails, the system understands, recuperates, and keeps logs for audit.
They progress with change, make it through audits, and provide structured data where it matters. This is why contemporary information groups no longer buy scrapersthey build infrastructure.
A lot of break under pressurescripts stall, proxies fail, selectors wander, and compliance breaks quietly. To avoid this, teams require more than tools. They need the ideal facilities of web scrapingbuilt for control, not just code execution. Tooling gives you gain access to. Facilities gives you ownership. The infrastructure of scraping systems specifies whether your data pipelines make it through legal change, traffic rises, and layout shifts.
Secret traits of a durable setup:: distributed queues, retry logic, and fault seclusion: every record has source, variation, and jurisdiction metadata: structure isn't patchedit's implemented at the point of capture: design variations trigger parser switches, not blackouts Without a governed, production-grade infrastructure of data scraping, expenses rise invisibly: Information gets re-cleaned in downstream systems Analysts question accuracy Legal groups rush throughout audits You don't need more toolsyou need an incorporated facilities of web scraping that supports scale, jurisdiction reasoning, and long-term reuse.
Not fast fixes, however systems that last.
Modern Private Web Extraction Techniques and Systems
Rather of depending on one device or one script, tasks are managed by collaborated nodes throughout areas, improving fault tolerance and speed. This setup prevents system-wide failure when a single job breaks or when content changes mid-scrape. It's the only approach that guarantees constant, real-time data circulation at enterprise scalewithout everyday maintenance or manual recovery.
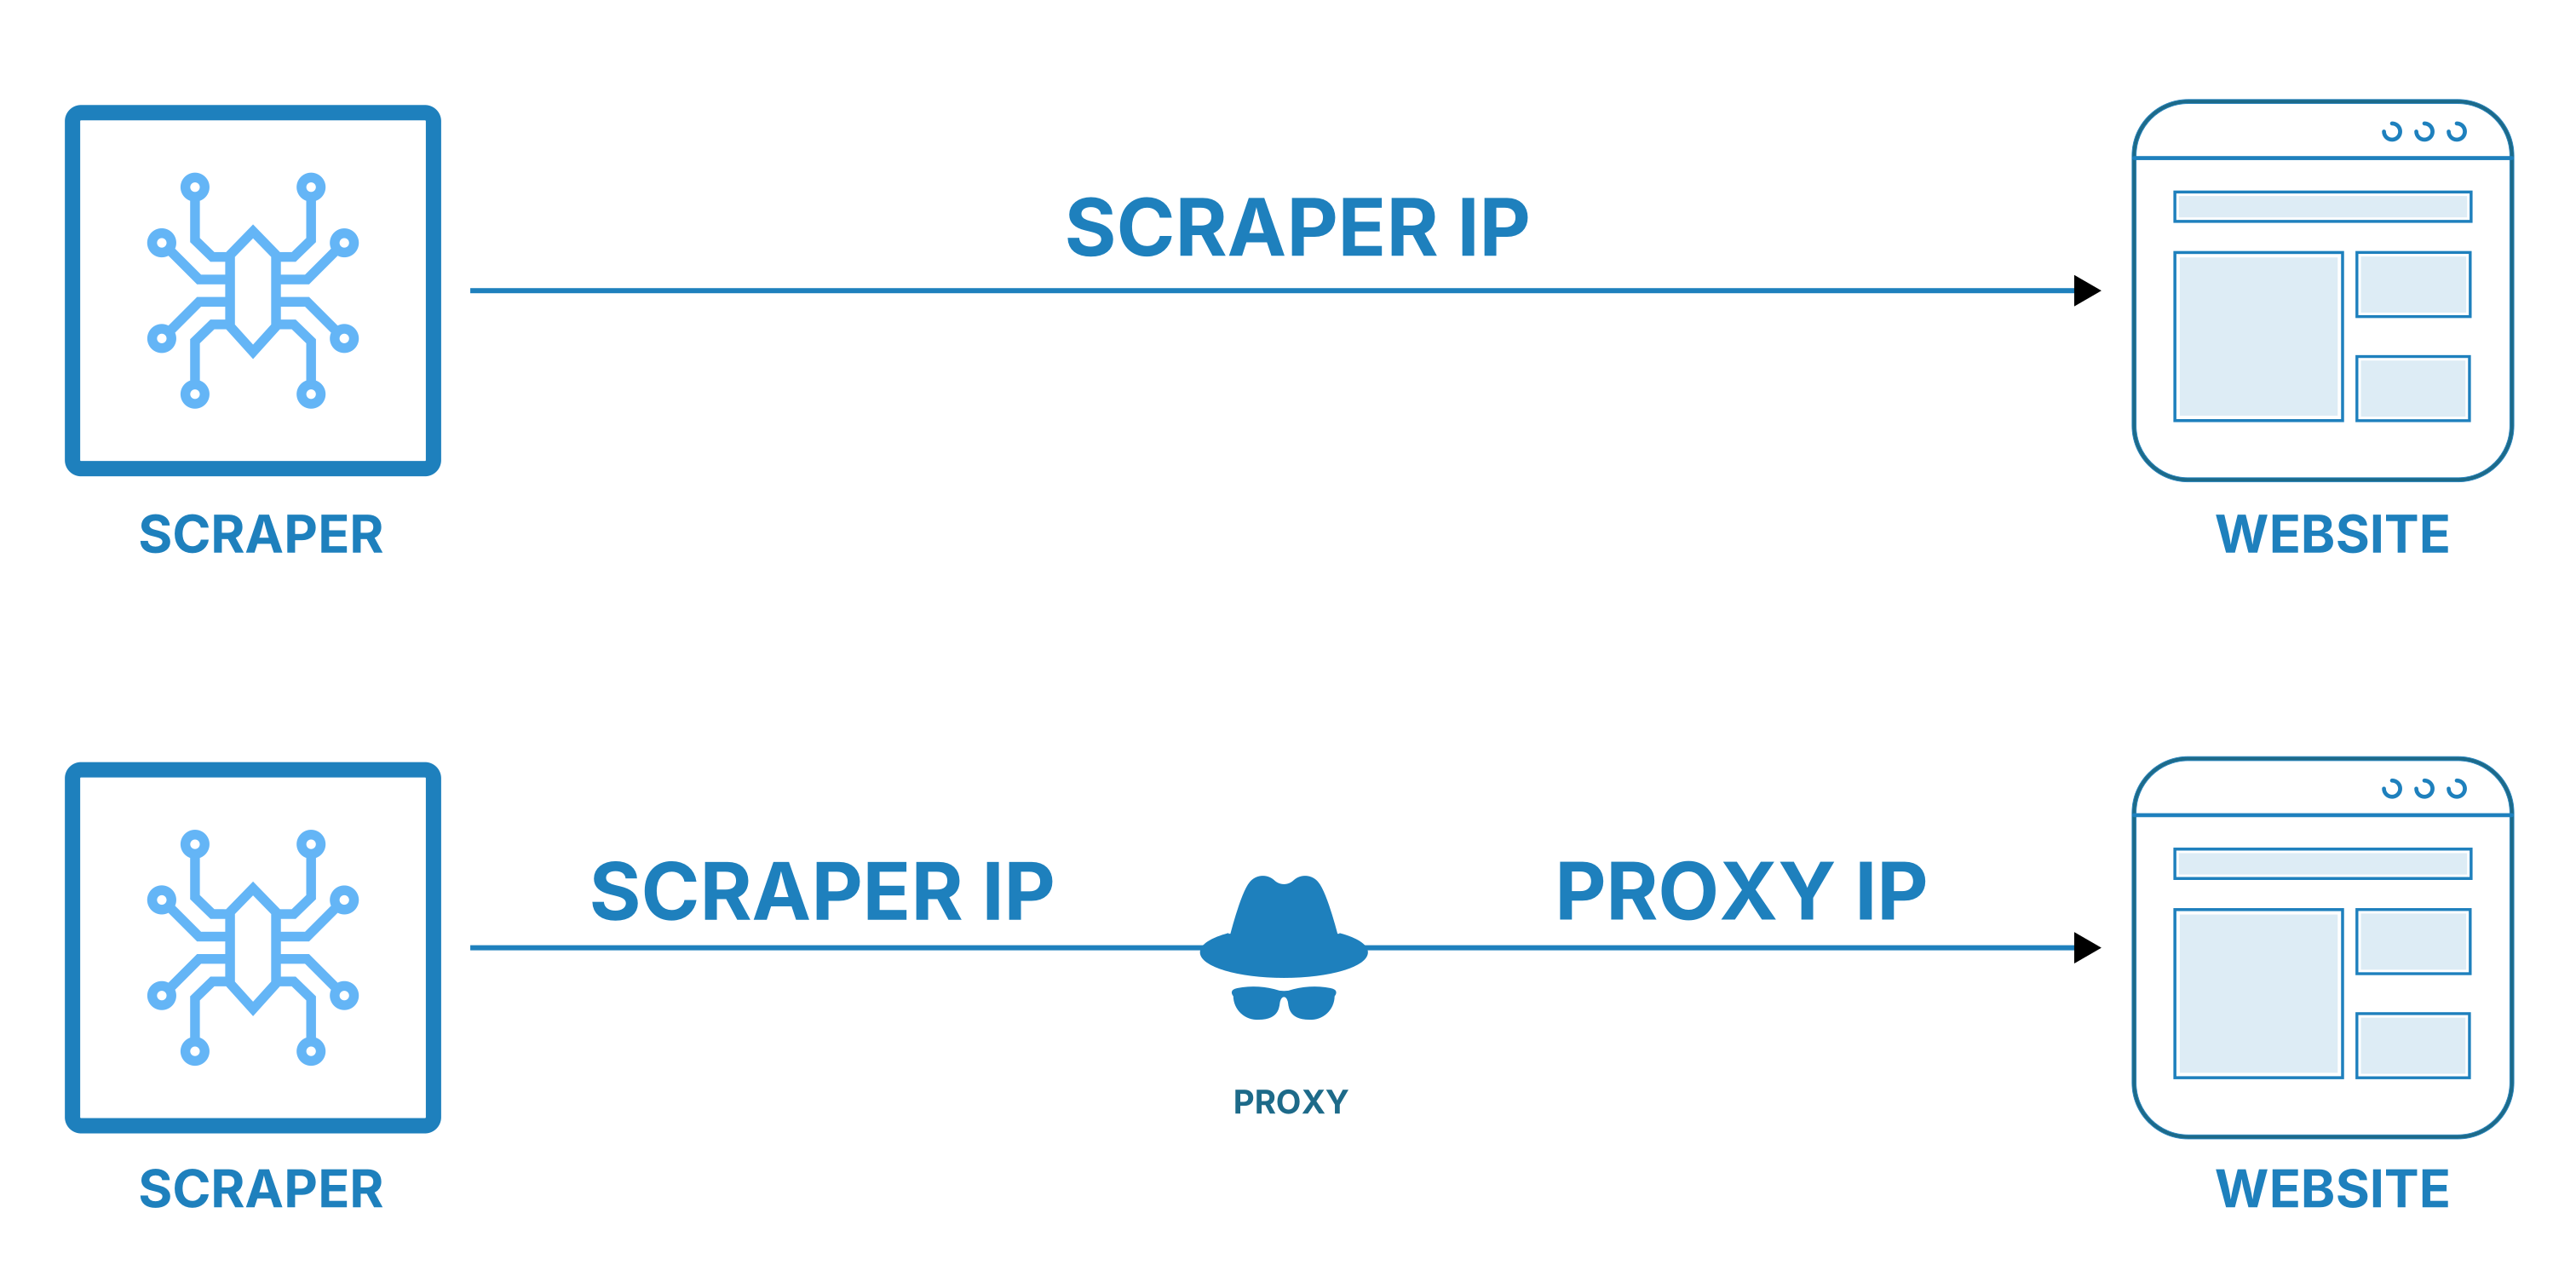
For any company tracking prices, inventory, listings, or news across markets, it's the only way to remain precise and ahead in genuine time. Rather than breaking, a durable facilities of web scraping finds design shifts and reroutes to backup parsers instantly. It flags disparities and generates brand-new rules without stopping the pipeline.
The result: undisturbed information flow. Structured scraping systems deliver tidy, labeled, and licensed information tagged by item, area, and usage rights.
proxy service tutorialsBuilding a powerful and scalable web scraping facilities requires an advanced system and meticulous preparation. First, you need to get a team of skilled developers, then you need to set up the infrastructure. Lastly, you require a rigorous round of testing before you are great to begin data extraction. Nevertheless one of the most challenging parts remains the scraping infrastructure.
proxy service tutorialsFor this reason, today we will be discussing some important elements of a robust and well-planned web scraping facilities. When scraping websites, particularly in bulk, you require some sort of automated scripts (normally called spiders) that need to be set up. These spiders ought to be able to produce several threads and act independently so that they can crawl multiple web pages at a time.
Deploying Affordable Backconnect Proxies for 2026
State you wish to crawl information from an e-commerce website called Now let's state Zuba has several subcategories such as books, clothes, watches, and smart phones. Once you reach the root site, (which can be ), you would like to develop 4 different spiders (one for web pages beginning with, one for those beginning with and so on).
They might increase more in case there are subcategories under each category. These spiders can crawl data individually and in case among them crashes due to an uncaught exception, you can resume it individually without disrupting all the other ones. The production of spiders would likewise assist you to crawl data at set time periods so that your information is constantly revitalized.
Web scraping does not suggest "event and discarding" of data. You should have validations and checks in place to make certain that unclean data does not end up in your datasets rendering them worthless. In case you are scraping information to fill particular data-points, you should be having restrictions for each data point.
For names, you can inspect if they include one or more words and are separated by areas. In this way, you can make certain that unclean or corrupt data do not sneak into your data-columns. Before you set about finalizing your web scraping structure, you ought to put in significant research to check which one offers the maximum data precision since that will cause much better outcomes and less requirement for manual intervention in the long run.