Optimizing High-Bandwidth Extraction Networks in 2026
Duplicates boost. Values normalize incorrectly. Protection drops in particular regions. Edge cases begin dominating the dataset. Without quality checks, this appears like normal variation. With quality checks, it appears like an early caution. Facilities allows you to specify expectations and monitor variances. Scripts usually simply collect whatever comes back. At scale, scraping raises questions beyond engineering.
They need logging, lineage, metadata, and documented behavior. This becomes especially important when scraped data feeds AI systems. When data influences models, traceability matters. Facilities supports this. Scripts do not. A basic test helps clarify the distinction. If scraping breaks at 3 A.M., will you understand what took place before users or stakeholders complain? Could you please let me know which source failed, when it failed, and how much data is affected? If the response is no, you have scripts running in the dark.
Observability is not an additional feature. It is the foundation of trust at scale. Many teams do not avoid facilities due to the fact that they are careless. They prevent it since scripts feel faster. Infrastructure feels heavy and sluggish at the beginning. This tradeoff is temporary. Every shortcut taken early appears later as rework, firefighting, and loss of confidence.
Scaling High-Bandwidth Crawling Networks in 2026
The only question is whether they do it deliberately or under pressure. At scale, scraping infrastructure usually consists of centralized scheduling, source-aware crawling, rate and behavior control, proxy and identity management, recognition layers, monitoring, notifying, lineage tracking, and recovery workflows. Scripts still exist inside this setup. They run within limits that make them safe and foreseeable.
The objective is to stop depending upon them alone. Web scraping is no longer a side project. It feeds rates systems, market analysis, forecasting, and AI training. When scraping stops working, genuine decisions are affected. As the worth of web data increases, so does the cost of getting it incorrect. Facilities lowers that risk.

It is about developing systems that survive change. Facilities is what makes it trustworthy. Groups that understand this early develop data pipelines they can rely on.
Companies that when relied on basic page parsers now need full systems that extract, structure, and deliver data in genuine timeacross geographies, platforms, and compliance limits. Tradition scraping toolslike fundamental crawlers and fixed selectorsfail under pressure.
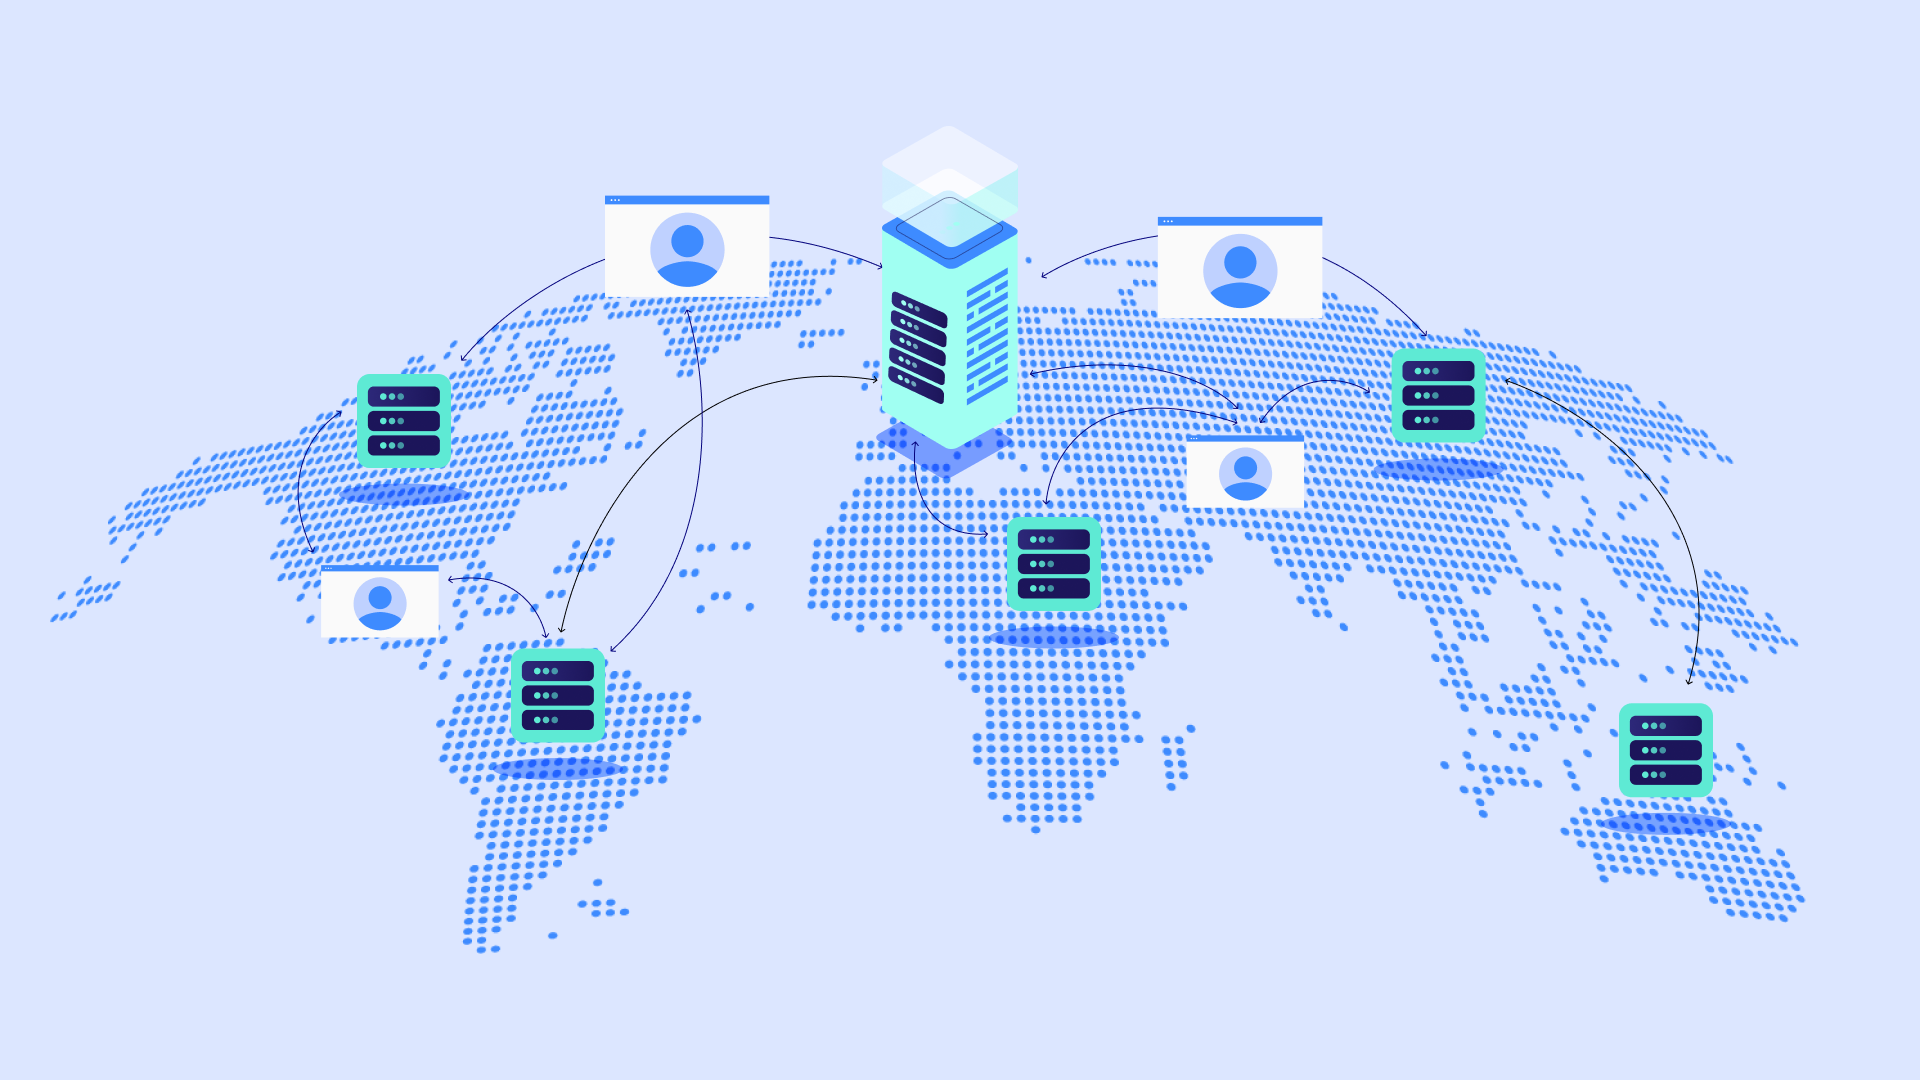
Most importantly, they can't satisfy business requirements: No fault tolerance No schema enforcement No shipment ensures Distributed web scraping systems are constructed for scale. They split the scraping pipeline into clear layerscrawling, queuing, changing, and deliveringand scale every one independently. These systems adapt dynamically: If a node stops working, traffic reroutes.
run SEO tools without getting blockedKey System Steps for Reliable Web Scraping
Modern scraping infrastructure doesn't simply runit recovers, preserves schema, imposes access controls, and incorporates cleanly into downstream systems. This is the difference in between break-fix scripts and production-grade infrastructure.
Market data shows the pattern. Many development projections track scraping software application. However software application alone doesn't resolve scale, compliance, or pipeline reliability. Numerous tools stop working to reflect the concealed invest on internal facilities or outsourced data pipelines. Market leaders now buy infrastructure, not just tools. Straits Research: $718.86 M in 2024 $2B by 2033 (13.29% CAGR) Research Study Nester: $703.56 M in 2024 $3.52 B by 2037 (13.2% CAGR) Mordor Intelligence: $1.03 B in 2025 $2B by 2030 (14.2% CAGR) These figures include business tools, handled services, and platform-scale builds.
This concentrate on durability has actually led many companies to transition from internal scripts to handled services, seeing the process as a dependable instance of web scraping as a service. Scraping has actually moved from the developer desk to the conference room. Companies now view it as a data supply chainsomething that need to be observable, repeatable, and certified.
Modern web data scraping infrastructure is layered by style. Each layer manages a specific functioningestion, transformation, governance, or deliveryand needs to scale individually. What follows is a practical blueprint of how distributed scraping architectures ought to be constructed for resilience, reuse, and real-time operations. Without this modular structure, the infrastructure of scraping systems stops working under pressure.
They develop crawl traffic jams, drop jobs under load, and stop working throughout time zones or areas. Distributed crawling uses message lines (e.g., Redis, RabbitMQ) and parallel workers to split crawl jobs across nodes: Jobs are designated by priority Failures are retried automatically Regions and load are well balanced dynamically Scraping becomes flexible and fault-tolerant.