Modern Private Information Extraction Techniques and Stacks

The governance structure for this pipeline uses logic created for a HIPAA-compliant platform for EHRs to enforce stringent patient information personal privacy. A logistics tech firm needed to gather route prices and service times from 50+ freight platforms in near actual time. The legacy system could not manage schedule shifts or dynamic ZIP-based quotes.
This complex, dynamic collection resembles the obstacles get rid of in scraping delivery pricing competitive intelligence for e-commerce logistics. A property investment platform required zoning approvals, allows, and live listings across 300+ city, local, and national sites. Inputs ranged from PDFs to outdated CMS templates. We deployed a system with: Layered spiders targeting registry, listings, and zoning divisions Field-based mapping for address, unit type, and allow stage Information validation versus historical maps and tax records Now, acquisition groups receive structured updates daily, with listing-to-market lag decreased by 67%.
Each system above was customized using a dispersed web scraping, enhanced for the scale, compliance, and lifecycle needs of its market. While their sources and objectives vary, the foundation is the very same: Tidy input.
Benefits of Automatic IP Nodes for Teams
Even the best-designed scraping systems face external volatilityanti-bot escalations, structural page shifts, rate limitations, and unforeseeable latency across regions. The challenge isn't simply gathering information.
Without vibrant queuing, retry storms overload systems. What's legal to extract in one area may be restricted in another.
To counter this, the infrastructure of data scraping need to evolve beyond scripts and ad-hoc retries. It must support dynamic reasoning, metadata tagging, and graceful degradation developed into every layer. We engineer scraping systems to perform under production-grade restrictions: Task circulations are decoupled and priority-driven, allowing quick rerouting under load. Fallback logic is activated based on predefined parser rules and versioning reasoning kept by our group.
Architecting Next-Gen Local Proxy Infrastructures
This web scraping infrastructure doesn't just fix what's brokenit prevents quiet decay. When a scraper fails, the system understands, recovers, and keeps logs for audit.
They develop with change, make it through audits, and provide structured data where it matters. This is why contemporary data groups no longer purchase scrapersthey construct infrastructure.
They need the right infrastructure of web scrapingbuilt for control, not simply code execution. Facilities offers you ownership. The facilities of scraping systems defines whether your data pipelines endure legal change, traffic surges, and design shifts.
Key characteristics of a resistant setup:: distributed lines, retry logic, and fault isolation: every record has source, version, and jurisdiction metadata: structure isn't patchedit's imposed at the point of capture: layout versions set off parser switches, not failures Without a governed, production-grade facilities of data scraping, costs rise invisibly: Data gets re-cleaned in downstream systems Experts question precision Legal groups rush throughout audits You do not need more toolsyou need an incorporated infrastructure of web scraping that supports scale, jurisdiction reasoning, and long-term reuse.
Not fast fixes, but systems that last. Advanced parsing tasks can even be sped up by utilizing innovative language models, as checked out in web scraping with ChatGPT workflows for data processing. Reserve a 30-minute consultation with GroupBWT to map your present scraping stack, identify weak links, and see what infrastructure-first delivery looks like.
Ways to Establish Resilient Dedicated Proxy Servers
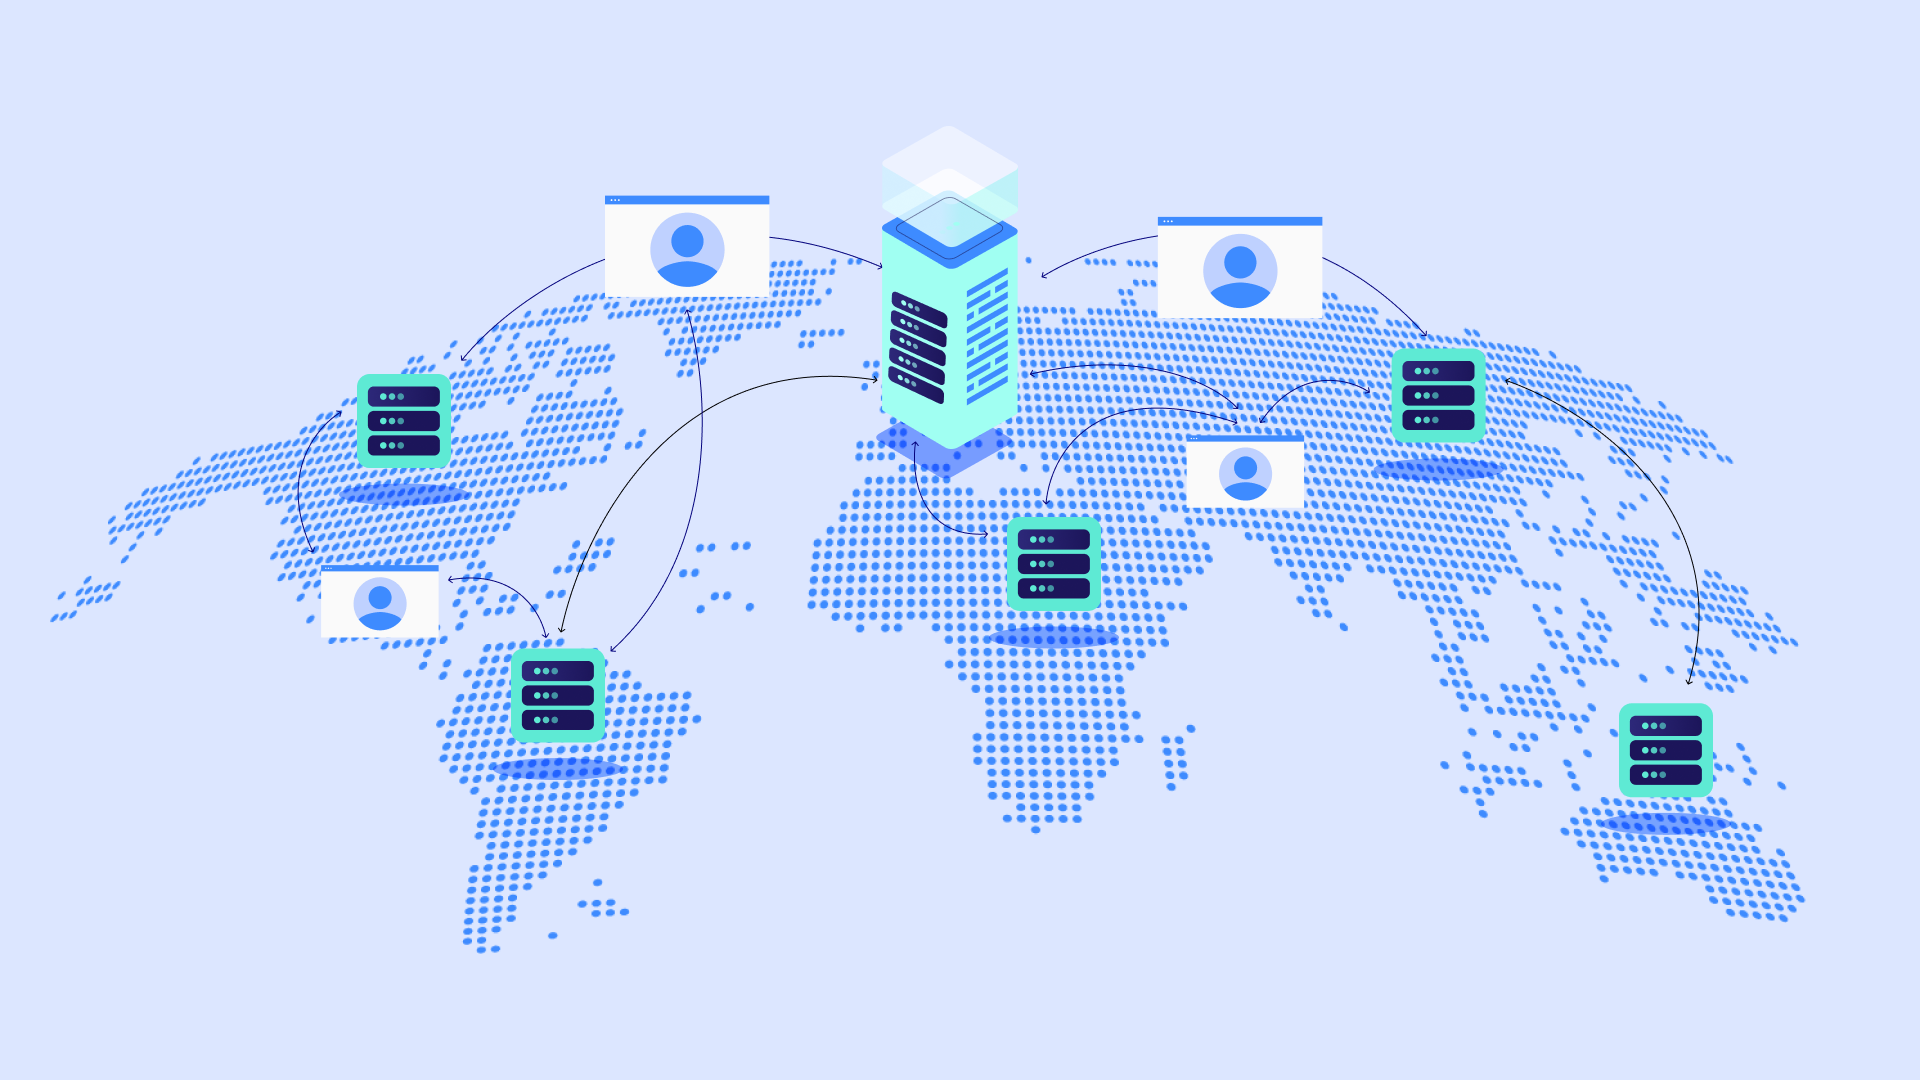
Rather of depending on one maker or one script, jobs are managed by collaborated nodes across areas, enhancing fault tolerance and speed. This setup avoids system-wide failure when a single job breaks or when content modifications mid-scrape. It's the only approach that guarantees continuous, real-time data circulation at enterprise scalewithout daily maintenance or manual healing.
For any company tracking prices, inventory, listings, or news across markets, it's the only way to stay precise and ahead in real time. Instead of breaking, a resilient facilities of web scraping identifies layout shifts and reroutes to backup parsers immediately. It flags disparities and generates new rules without stopping the pipeline.
The outcome: continuous information circulation. Structured scraping systems deliver tidy, identified, and certified data tagged by product, area, and usage rights.
You need a rigorous round of screening before you are good to start data extraction. One of the most difficult parts stays the scraping facilities.
choosing the right proxyFor this reason, today we will be talking about some vital elements of a robust and well-planned web scraping infrastructure. When scraping sites, specifically wholesale, you need some sort of automated scripts (typically called spiders) that require to be established. These spiders need to have the ability to create several threads and act independently so that they can crawl multiple web pages at a time.
Impacts of Automatic Proxy Nodes for Teams
State you desire to crawl information from an e-commerce site called Now let's say Zuba has several subcategories such as books, clothes, watches, and mobile phones. When you reach the root site, (which can be ), you would like to produce 4 various spiders (one for websites starting with, one for those starting with and so on).
They might multiply more in case there are subcategories under each classification. These spiders can crawl data separately and in case one of them crashes due to an uncaught exception, you can resume it separately without interrupting all the other ones. The development of spiders would also help you to crawl information at fixed time intervals so that your information is always revitalized.
Web scraping does not imply "event and dumping" of data. You ought to have recognitions and checks in location to make certain that dirty data does not wind up in your datasets rendering them ineffective. In case you are scraping information to fill particular data-points, you must be having restrictions for each information point.
For names, you can examine if they consist of several words and are separated by areas. In this method, you can make sure that dirty or corrupt data do not sneak into your data-columns. Before you set about completing your web scraping structure, you should put in significant research study to inspect which one provides the maximum information accuracy because that will lead to much better outcomes and less requirement for manual intervention in the long run.