Maximizing Extraction Speeds With Backconnect Nodes
A logistics tech company needed to collect route prices and service times from 50+ freight platforms in near genuine time. The tradition system couldn't handle schedule shifts or dynamic ZIP-based quotes.
This complex, vibrant collection resembles the obstacles overcome in scraping shipment prices competitive intelligence for e-commerce logistics. A residential or commercial property investment platform needed zoning approvals, permits, and live listings across 300+ city, community, and national sites. Inputs varied from PDFs to outdated CMS design templates. We released a system with: Layered crawlers targeting pc registry, listings, and zoning divisions Field-based mapping for address, system type, and permit stage Information validation versus historical maps and tax records Now, acquisition groups get structured updates daily, with listing-to-market lag decreased by 67%.
The system's core abilities, including information recognition and structuring, are supplied by specialized data engineering services & services that concentrate on data stability. Each system above was customized utilizing a distributed web scraping, enhanced for the scale, compliance, and lifecycle demands of its market. While their sources and goals differ, the structure is the very same: Tidy input.
Scalable Harvesting Workflows for Global Web Projects
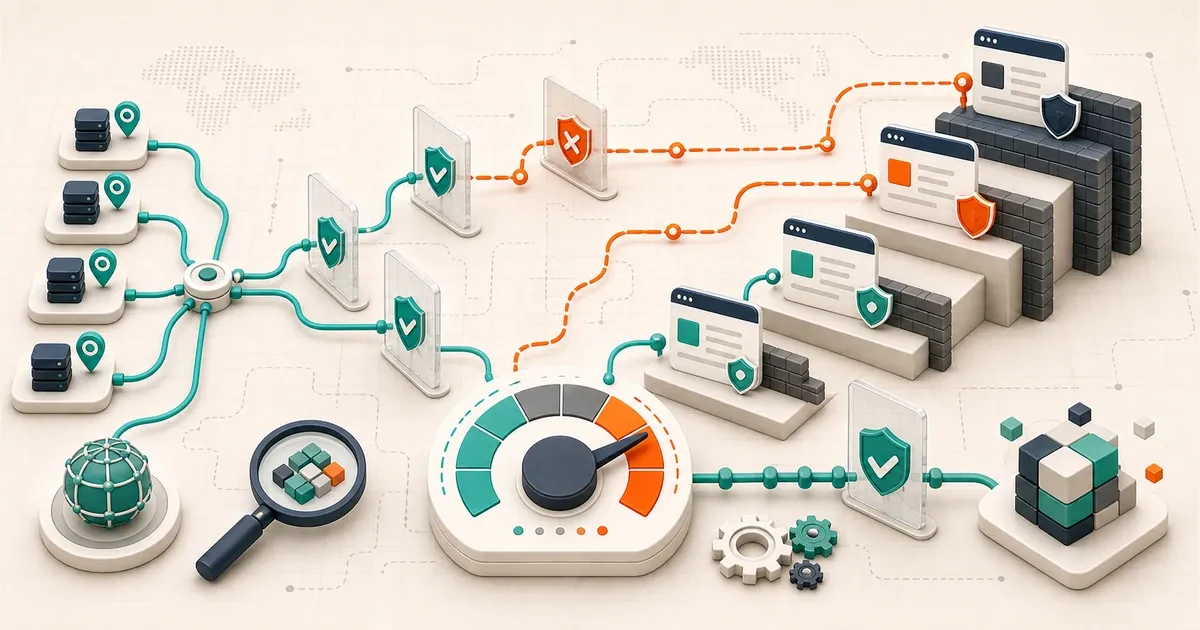
Even the best-designed scraping systems face external volatilityanti-bot escalations, structural page shifts, rate limitations, and unforeseeable latency throughout areas. The difficulty isn't just collecting data.
Without dynamic queuing, retry storms overload systems. What's legal to extract in one region might be limited in another.
To counter this, the facilities of data scraping should evolve beyond scripts and ad-hoc retries. It must support vibrant logic, metadata tagging, and elegant degradation constructed into every layer. We craft scraping systems to perform under production-grade restrictions: Task circulations are decoupled and priority-driven, permitting fast rerouting under load. Fallback reasoning is activated based upon predefined parser rules and versioning reasoning kept by our team.
How to Establish High-Performance Internal Proxy Infrastructures
This web scraping facilities does not simply fix what's brokenit avoids silent decay. When a scraper fails, the system knows, recuperates, and keeps logs for audit.
They progress with change, make it through audits, and deliver structured information where it matters. This is why contemporary information groups no longer purchase scrapersthey construct facilities.
They need the best facilities of web scrapingbuilt for control, not just code execution. Facilities offers you ownership. The facilities of scraping systems defines whether your information pipelines make it through legal change, traffic rises, and design shifts.
Secret traits of a resilient setup:: dispersed queues, retry reasoning, and fault isolation: every record has source, variation, and jurisdiction metadata: structure isn't patchedit's enforced at the point of capture: layout versions trigger parser switches, not failures Without a governed, production-grade facilities of information scraping, costs rise undetectably: Information gets re-cleaned in downstream systems Analysts question precision Legal groups rush throughout audits You do not need more toolsyou require an integrated infrastructure of web scraping that supports scale, jurisdiction logic, and long-term reuse.
Not fast fixes, however systems that last. Sophisticated parsing jobs can even be sped up by utilizing sophisticated language models, as checked out in web scraping with ChatGPT workflows for data processing. Reserve a 30-minute consultation with GroupBWT to map your current scraping stack, identify weak spots, and see what infrastructure-first shipment appears like.
Benefits of Backconnect IP Setups for Businesses
Instead of relying on one maker or one script, tasks are dealt with by collaborated nodes throughout places, improving fault tolerance and speed. This setup avoids system-wide failure when a single task breaks or when content changes mid-scrape. It's the only method that ensures continuous, real-time information circulation at enterprise scalewithout everyday upkeep or manual recovery.
For any business tracking rates, stock, listings, or news across markets, it's the only way to stay accurate and ahead in genuine time. Rather than breaking, a durable infrastructure of web scraping spots layout shifts and reroutes to backup parsers instantly. It flags inconsistencies and generates brand-new guidelines without stopping the pipeline.
The result: undisturbed information flow. Structured scraping systems provide tidy, labeled, and accredited data tagged by item, region, and use rights.
proxies for website growthBuilding a powerful and scalable web scraping facilities requires a sophisticated system and careful preparation. You require to get a group of skilled developers, then you require to set up the facilities. Finally, you need a strenuous round of screening before you are excellent to start data extraction. One of the most challenging parts remains the scraping facilities.
proxies for website growthHence, today we will be talking about some crucial parts of a robust and well-planned web scraping infrastructure. When scraping websites, particularly wholesale, you need some sort of automated scripts (usually called spiders) that require to be established. These spiders need to be able to develop numerous threads and act individually so that they can crawl multiple websites at a time.
Scalable Harvesting Workflows for Massive Web Projects
Say you desire to crawl information from an e-commerce site called Now let's say Zuba has multiple subcategories such as books, clothing, watches, and mobile phones. As soon as you reach the root site, (which can be ), you would like to produce 4 different spiders (one for webpages starting with, one for those starting with and so on).
They might multiply more in case there are subcategories under each classification. These spiders can crawl data individually and in case one of them crashes due to an uncaught exception, you can resume it separately without disrupting all the other ones. The development of spiders would likewise help you to crawl data at fixed time intervals so that your data is constantly revitalized.
Web scraping does not suggest "gathering and disposing" of data. You need to have validations and checks in location to ensure that dirty data does not end up in your datasets rendering them useless. In case you are scraping data to fill up particular data-points, you must be having constraints for each data point.
For names, you can check if they include one or more words and are separated by spaces. In this way, you can make sure that filthy or corrupt information do not creep into your data-columns. Before you tackle finalizing your web scraping structure, you should put in considerable research study to inspect which one provides the maximum information precision since that will lead to better results and less requirement for manual intervention in the long run.












