Key System Decisions for Reliable Automated Scraping
Infrastructure allows you to specify expectations and keep an eye on variances. Scripts normally simply gather whatever comes back. At scale, scraping raises concerns beyond engineering.
This becomes specifically crucial when scraped information feeds AI systems. As soon as data influences models, traceability matters. Could you please let me know which source failed, when it failed, and how much data is affected?
Many teams do not prevent facilities since they are careless. They prevent it because scripts feel much faster. Infrastructure feels heavy and sluggish at the start.
Comparing Internal and Residential Proxy Setups
The only concern is whether they do it intentionally or under pressure. At scale, scraping infrastructure generally consists of centralized scheduling, source-aware crawling, rate and habits control, proxy and identity management, recognition layers, monitoring, informing, lineage tracking, and recovery workflows. Scripts still exist inside this setup. They run within boundaries that make them safe and foreseeable.
The objective is to stop depending on them alone. Web scraping is no longer a side project. It feeds prices systems, market analysis, forecasting, and AI training. When scraping fails, genuine decisions are affected. As the value of web data boosts, so does the cost of getting it wrong. Facilities lowers that threat.
It has to do with constructing systems that endure change. Scripts can begin the journey. Facilities is what makes it trusted. Groups that comprehend this early build data pipelines they can rely on. Teams that do not usually discover it later on, when the cost is much greater. Cheers, guys, see you next time.
Web scraping infrastructure has changed manual scripts as the foundation of scalable big information operations. Companies that when relied on basic page parsers now require full systems that extract, structure, and provide data in genuine timeacross geographies, platforms, and compliance boundaries. Legacy scraping toolslike basic crawlers and fixed selectorsfail under pressure.
Most notably, they can't fulfill enterprise requirements: No fault tolerance No schema enforcement No delivery guarantees Dispersed web scraping systems are developed for scale. They divided the scraping pipeline into clear layerscrawling, queuing, changing, and deliveringand scale each one independently. These systems adapt dynamically: If a node fails, traffic reroutes.
run SEO tools without getting blockedStrategic Advice for Managing Cheap Proxy Setups
Modern scraping infrastructure doesn't simply runit recuperates, maintains schema, enforces access controls, and integrates easily into downstream systems. This is the distinction in between break-fix scripts and production-grade infrastructure.
Market data proves the trend. Many growth forecasts track scraping software. Many tools stop working to reflect the covert invest on internal facilities or outsourced information pipelines.
run SEO tools without getting blocked
This concentrate on resilience has led numerous companies to transition from in-house scripts to handled services, viewing the process as a dependable circumstances of web scraping as a service. Scraping has moved from the designer desk to the conference room. Companies now view it as a data supply chainsomething that should be observable, repeatable, and certified.
Modern web data scraping infrastructure is layered by style. Without this modular structure, the infrastructure of scraping systems stops working under pressure.
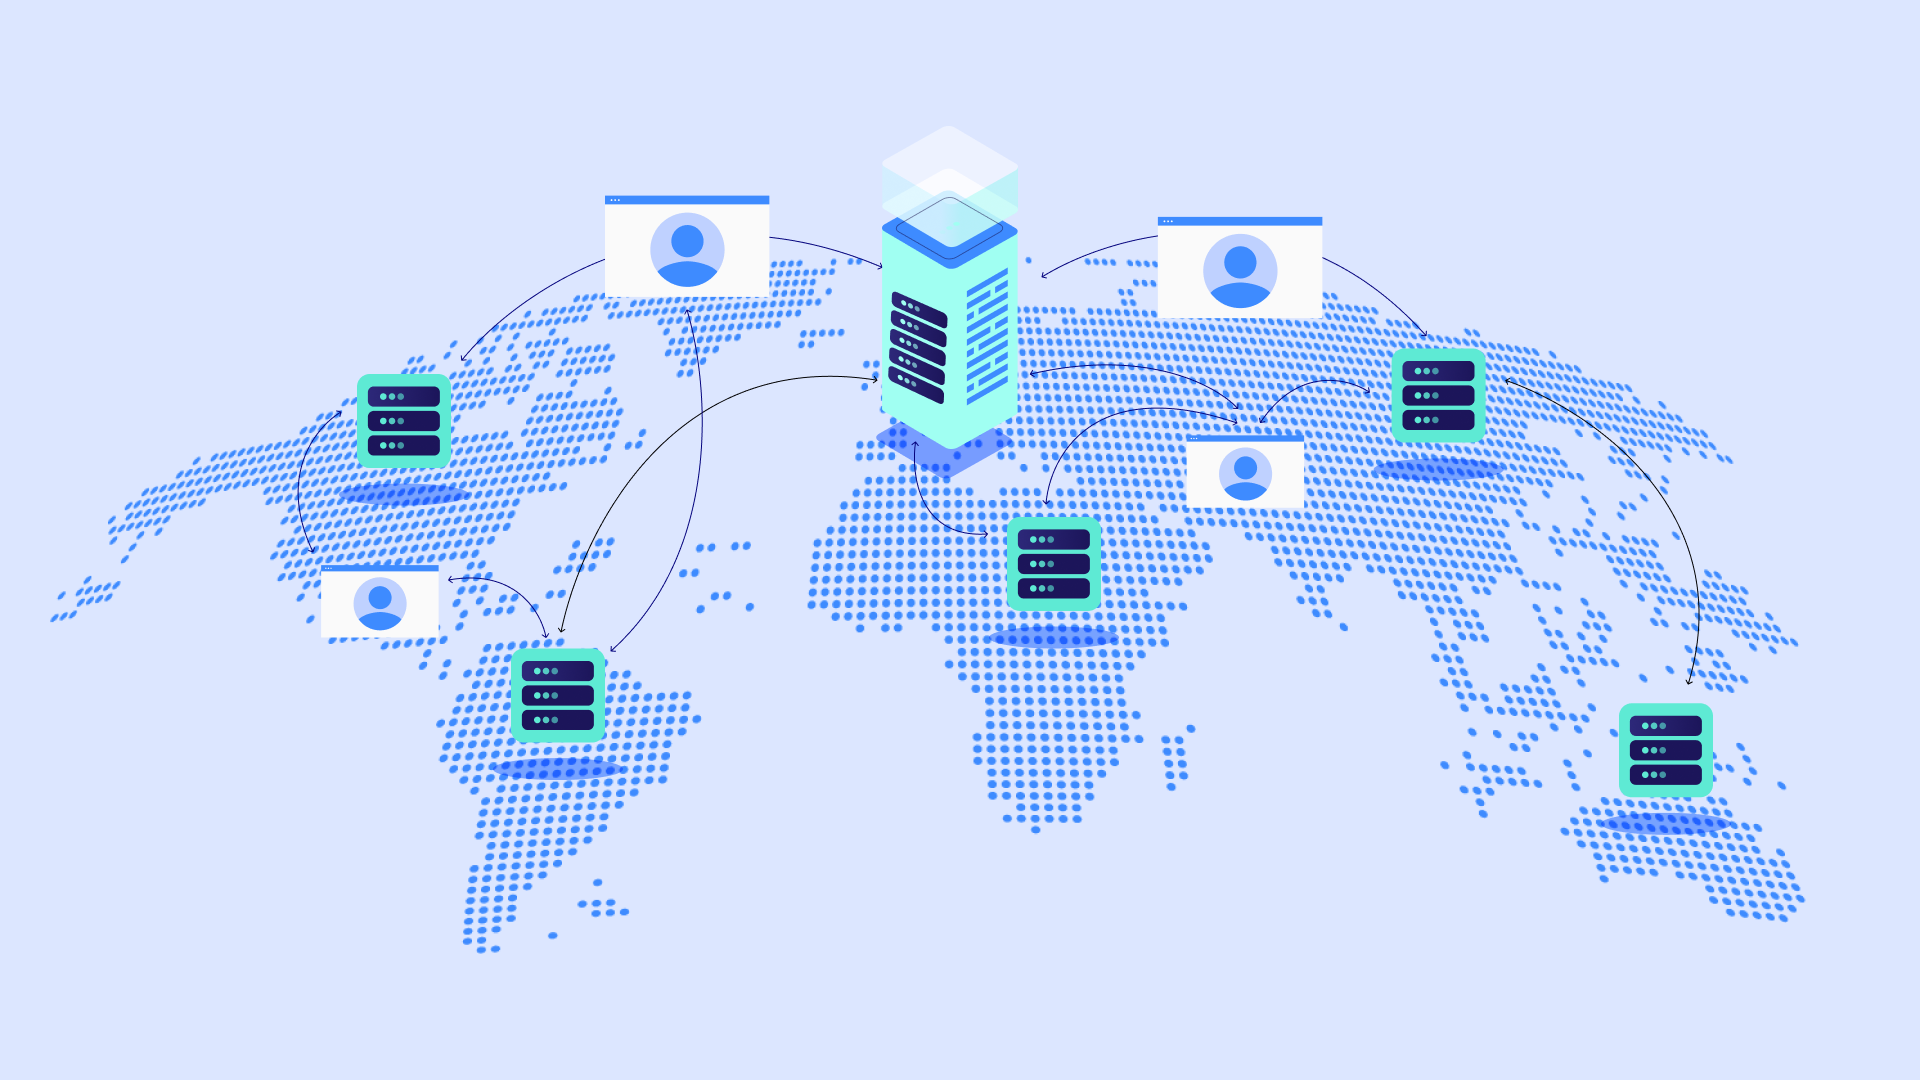
They produce crawl bottlenecks, drop tasks under load, and fail across time zones or regions. Dispersed crawling usages message lines (e.g., Redis, RabbitMQ) and parallel workers to divide crawl jobs throughout nodes: Jobs are assigned by concern Failures are retried instantly Regions and load are well balanced dynamically Scraping ends up being flexible and fault-tolerant.