Increasing Bot Rates With Residential Nodes

; HttpRequest demand = HttpRequest.newBuilder(). POST(HttpRequest.
BodyHandlers.ofString()); (()); utilizing var customer = brand-new HttpClient(); client. DefaultRequestHeaders. Authorization = brand-new AuthenticationHeaderValue("Bearer", "YOUR_API_KEY"); var payload = new sitemap_id = 123, request_interval = 2000, page_load_delay = 2000, proxy="datacenter-us", start_urls = brand-new [] "", ""; var response = await client. PostAsJsonAsync( "", payload ); var content = wait for reaction.
The majority of web scraping tasks start with a script. Someone writes a couple of lines of code, runs it versus a site, and information appears in a file or database. For a while, everything looks fine. The script runs. The data updates. Individuals proceed. This early success develops a false sense of self-confidence.
In truth, that script is only fixing the smallest part of the problem. It shows you can draw out information once. When scraping a few pages, working means the script runs without errors.
At scale, working means the data is appropriate today, tomorrow, and next month. It implies coverage does not silently drop. It indicates modifications are discovered early. It suggests failures are noticeable. It suggests teams trust the output enough to make choices with it. Scripts are not constructed for this meaning of working.
Setting Up Affordable Backconnect Nodes for 2026
Parsing is not what breaks scraping systems in production. What breaks systems are layout changes, partial failures, rate limits, blocking, retries, and quiet information shifts.
At scale, parsing is perhaps ten percent of the work. The most hazardous scraping failures are the ones you do not see.
In all of these cases, the script keeps running. Infrastructure can detect these patterns. Scripts can not, unless you keep including vulnerable checks that ultimately end up being uncontrollable.
Strategic Advice for Managing Budget Scraping Pools
They alter whenever the site owner desires. At scale, you are not scraping one site. You are scraping many throughout areas, classifications, and formats.
Scripts typically assume the world stays the same. The web never ever does. They enjoy request timing, frequency, headers, navigation circulation, and session behavior.
Infrastructure manages how those demands act over time. When scraping becomes crucial to the service, dependability expectations rise. People anticipate the data to be there every day.
Duplicates increase. Values normalize incorrectly. Coverage drops in certain areas. Edge cases begin dominating the dataset. Without quality checks, this appears like normal variation. With quality checks, it looks like an early caution. Facilities allows you to define expectations and keep track of variances. Scripts normally simply collect whatever returns. At scale, scraping raises questions beyond engineering.
Advantages of Backconnect Proxy Setups for Teams
They require logging, family tree, metadata, and documented behavior. This becomes specifically crucial when scraped data feeds AI systems. As soon as information influences designs, traceability matters. Facilities supports this. Scripts do not. A basic test helps clarify the distinction. If scraping breaks at 3 A.M., will you understand what occurred before users or stakeholders complain? Could you please let me know which source stopped working, when it stopped working, and just how much information is impacted? If the answer is no, you have scripts running in the dark.
GSA SER VPSMost groups do not prevent facilities because they are careless. They prevent it due to the fact that scripts feel faster. Infrastructure feels heavy and sluggish at the beginning.
The only question is whether they do it intentionally or under pressure. At scale, scraping infrastructure normally includes central scheduling, source-aware crawling, rate and habits control, proxy and identity management, recognition layers, tracking, notifying, lineage tracking, and recovery workflows. Scripts still exist inside this setup. They operate within limits that make them safe and foreseeable.
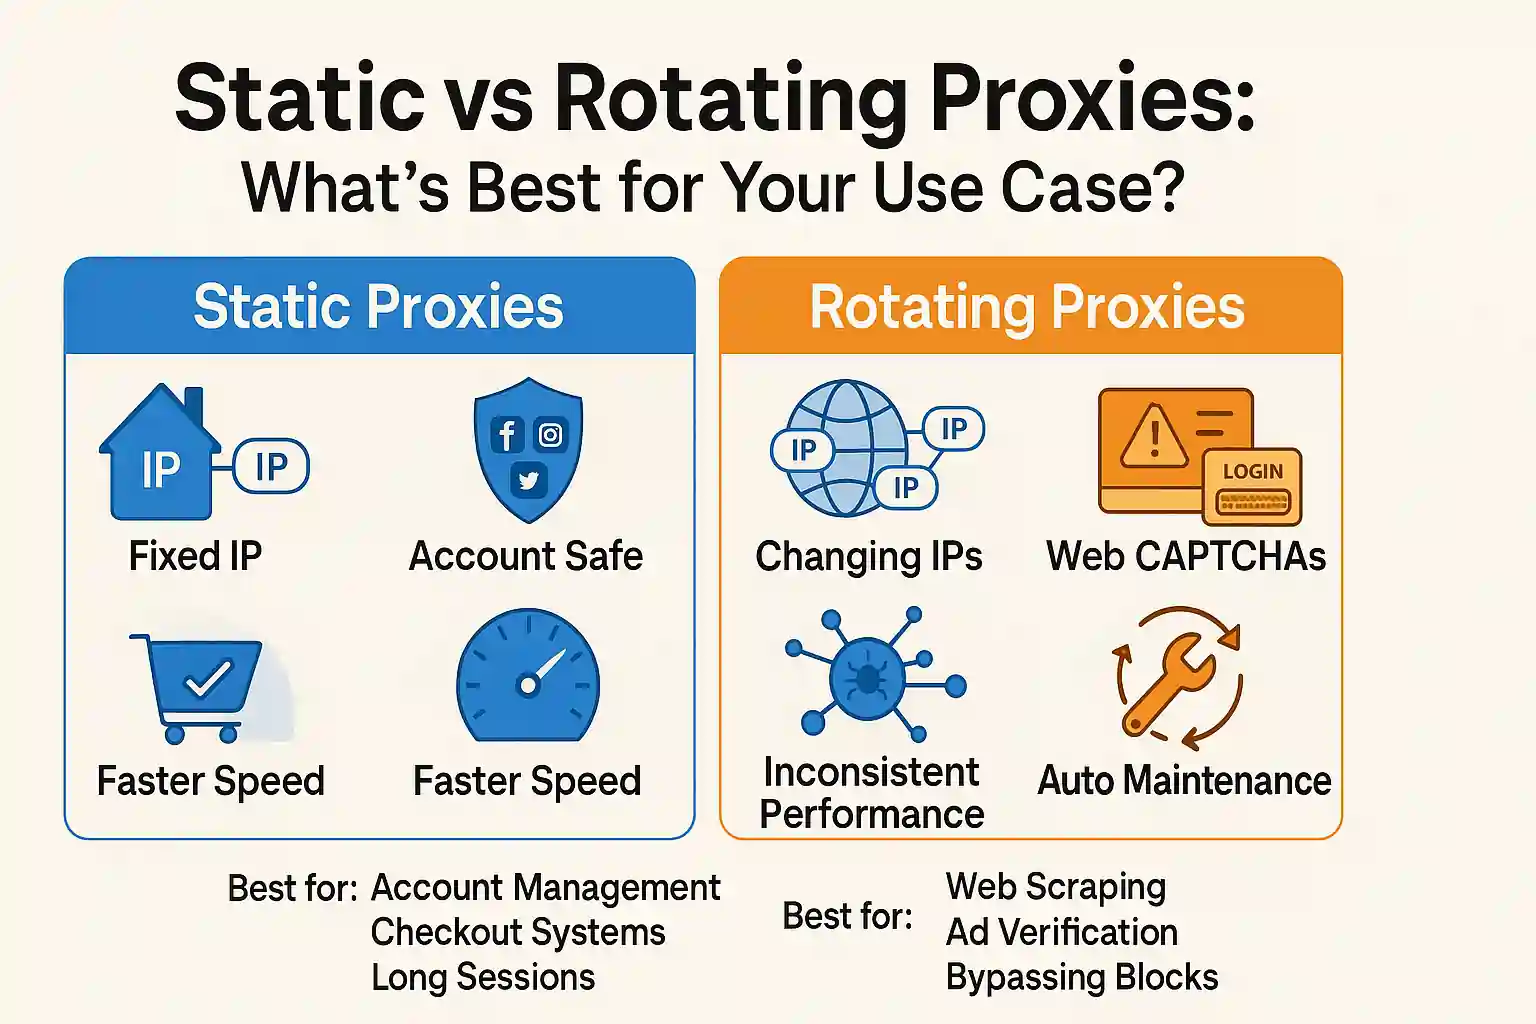
Comparing Private and Rotating IP Setups
The goal is to stop depending on them alone. Web scraping is no longer a side job. It feeds rates systems, market analysis, forecasting, and AI training. When scraping stops working, genuine decisions are impacted. As the worth of web data boosts, so does the expense of getting it wrong. Facilities minimizes that danger.
GSA SER VPSIt is about building systems that endure modification. Infrastructure is what makes it trustworthy. Teams that understand this early develop data pipelines they can trust.
Businesses that as soon as relied on easy page parsers now need full systems that draw out, structure, and deliver information in genuine timeacross geographies, platforms, and compliance borders. Legacy scraping toolslike fundamental spiders and static selectorsfail under pressure.
Most importantly, they can't meet business requirements: No fault tolerance No schema enforcement No shipment ensures Dispersed web scraping systems are built for scale. They split the scraping pipeline into clear layerscrawling, queuing, changing, and deliveringand scale each one independently. These systems adapt dynamically: If a node stops working, traffic reroutes.
If APIs obstruct, proxies turn. Governance, observability, and elastic scaling are baked into the architecture, not bolted on after the truth. The result is strength. Modern scraping facilities doesn't simply runit recuperates, maintains schema, enforces access controls, and integrates cleanly into downstream systems. This is the difference in between break-fix scripts and production-grade facilities.
Robust Harvesting Workflows for High-Volume Data Projects
Market information shows the trend. Many development forecasts track scraping software. Numerous tools stop working to show the hidden spend on internal infrastructure or outsourced information pipelines.
This concentrate on strength has led numerous firms to shift from internal scripts to managed services, seeing the process as a reliable circumstances of web scraping as a service. Scraping has actually moved from the developer desk to the boardroom. Companies now view it as a data supply chainsomething that should be observable, repeatable, and certified.
Modern web information scraping facilities is layered by design. Each layer manages a particular functioningestion, improvement, governance, or deliveryand needs to scale individually. What follows is a useful blueprint of how dispersed scraping architectures need to be constructed for durability, reuse, and real-time operations. Without this modular structure, the facilities of scraping systems fails under pressure.
How to Establish Resilient Internal Proxy Servers
They produce crawl traffic jams, drop tasks under load, and fail across time zones or regions. Distributed crawling uses message queues (e.g., Redis, RabbitMQ) and parallel workers to split crawl jobs throughout nodes: Jobs are designated by concern Failures are retried instantly Regions and load are balanced dynamically Scraping becomes flexible and fault-tolerant.