How Anonymized Tools Power Digital Mining
; HttpRequest demand = HttpRequest.newBuilder(). POST(HttpRequest.
BodyHandlers.ofString()); (()); utilizing var customer = new HttpClient(); client. DefaultRequestHeaders. Authorization = new AuthenticationHeaderValue("Bearer", "YOUR_API_KEY"); var payload = brand-new sitemap_id = 123, request_interval = 2000, page_load_delay = 2000, proxy="datacenter-us", start_urls = new [] "", ""; var reaction = await client. PostAsJsonAsync( "", payload ); var material = await action.
Many web scraping projects begin with a script. Someone composes a couple of lines of code, runs it versus a website, and data appears in a file or database. For a while, everything looks fine. The script runs. The data updates. Individuals carry on. This early success creates an incorrect sense of confidence.
In reality, that script is just resolving the smallest part of the issue. It shows you can extract information once. When scraping a few pages, working suggests the script runs without errors.
At scale, working indicates the data is appropriate today, tomorrow, and next month. It implies coverage does not quietly drop. It suggests changes are found early. It means failures show up. It suggests teams rely on the output enough to make decisions with it. Scripts are not built for this definition of working.
Architecting Next-Gen Local Proxy Networks
Many groups invest the majority of their early effort on selectors, XPath, or CSS rules. That effort feels efficient since it produces instant results. Parsing is not what breaks scraping systems in production. What breaks systems are design changes, partial failures, rate limitations, obstructing, retries, and silent data shifts. These issues live outside the parsing logic.
At scale, parsing is perhaps ten percent of the work. The most unsafe scraping failures are the ones you do not see.
In all of these cases, the script keeps running. Infrastructure can discover these patterns. Scripts can not, unless you keep including vulnerable checks that eventually become unmanageable.
Scaling Large-Scale Extraction Networks in 2026
They change whenever the website owner wants. A little UI experiment can break a scraper. A brand-new advertisement positioning can shift the DOM. A region-specific banner can alter page structure. At scale, you are not scraping one site. You are scraping lots of across regions, categories, and formats. The probability that something modifications every day is extremely high.
Scripts normally presume the world stays the same. The web never does. Modern sites hardly ever obstruct based upon code alone. They look at behavior patterns. They enjoy request timing, frequency, headers, navigation flow, and session habits. If your traffic looks abnormal, you get throttled, challenged, or served alternate content. Handling this is not about writing smarter parsing code.
These are facilities problems. A script can send requests. Facilities controls how those demands act gradually. When scraping becomes essential to the service, dependability expectations increase. Individuals anticipate the data to be there every day. They anticipate gaps to be described. They anticipate failures to be dealt with without manual intervention.
Duplicates boost. Worths stabilize incorrectly. Protection drops in specific areas. Edge cases start controling the dataset. Without quality checks, this looks like regular variation. With quality checks, it appears like an early caution. Facilities enables you to specify expectations and monitor discrepancies. Scripts typically just collect whatever comes back. At scale, scraping raises concerns beyond engineering.
Modern Private Web Harvesting Techniques and Strategies
They need logging, lineage, metadata, and recorded behavior. This becomes specifically essential when scraped information feeds AI systems. Once information affects designs, traceability matters. Infrastructure supports this. Scripts do not. A simple test assists clarify the difference. If scraping breaks at 3 A.M., will you understand what happened before users or stakeholders grumble? Could you please let me know which source stopped working, when it failed, and how much information is affected? If the answer is no, you have scripts running in the dark.
GSA SER VPS upgradeObservability is not an additional feature. It is the foundation of trust at scale. Most teams do not prevent infrastructure due to the fact that they are reckless. They prevent it since scripts feel much faster. Facilities feels heavy and sluggish at the beginning. This tradeoff is temporary. Every faster way taken early shows up later on as rework, firefighting, and loss of confidence.
At scale, scraping facilities generally consists of centralized scheduling, source-aware crawling, rate and habits control, proxy and identity management, recognition layers, monitoring, informing, family tree tracking, and recovery workflows. Scripts still exist inside this setup.
Increasing Scraping Success With Rotating Proxies
Web scraping is no longer a side project. When scraping fails, genuine choices are impacted. As the worth of web data increases, so does the expense of getting it incorrect.
GSA SER VPS upgradeIt is about constructing systems that endure modification. Facilities is what makes it reputable. Groups that comprehend this early build information pipelines they can trust.
Web scraping facilities has changed manual scripts as the structure of scalable huge data operations. Organizations that when depended on basic page parsers now need complete systems that extract, structure, and provide information in genuine timeacross geographies, platforms, and compliance limits. Tradition scraping toolslike basic spiders and static selectorsfail under pressure.
Most significantly, they can't fulfill business needs: No fault tolerance No schema enforcement No delivery guarantees Distributed web scraping systems are constructed for scale. They split the scraping pipeline into clear layerscrawling, queuing, changing, and deliveringand scale every one individually. These systems adapt dynamically: If a node fails, traffic reroutes.
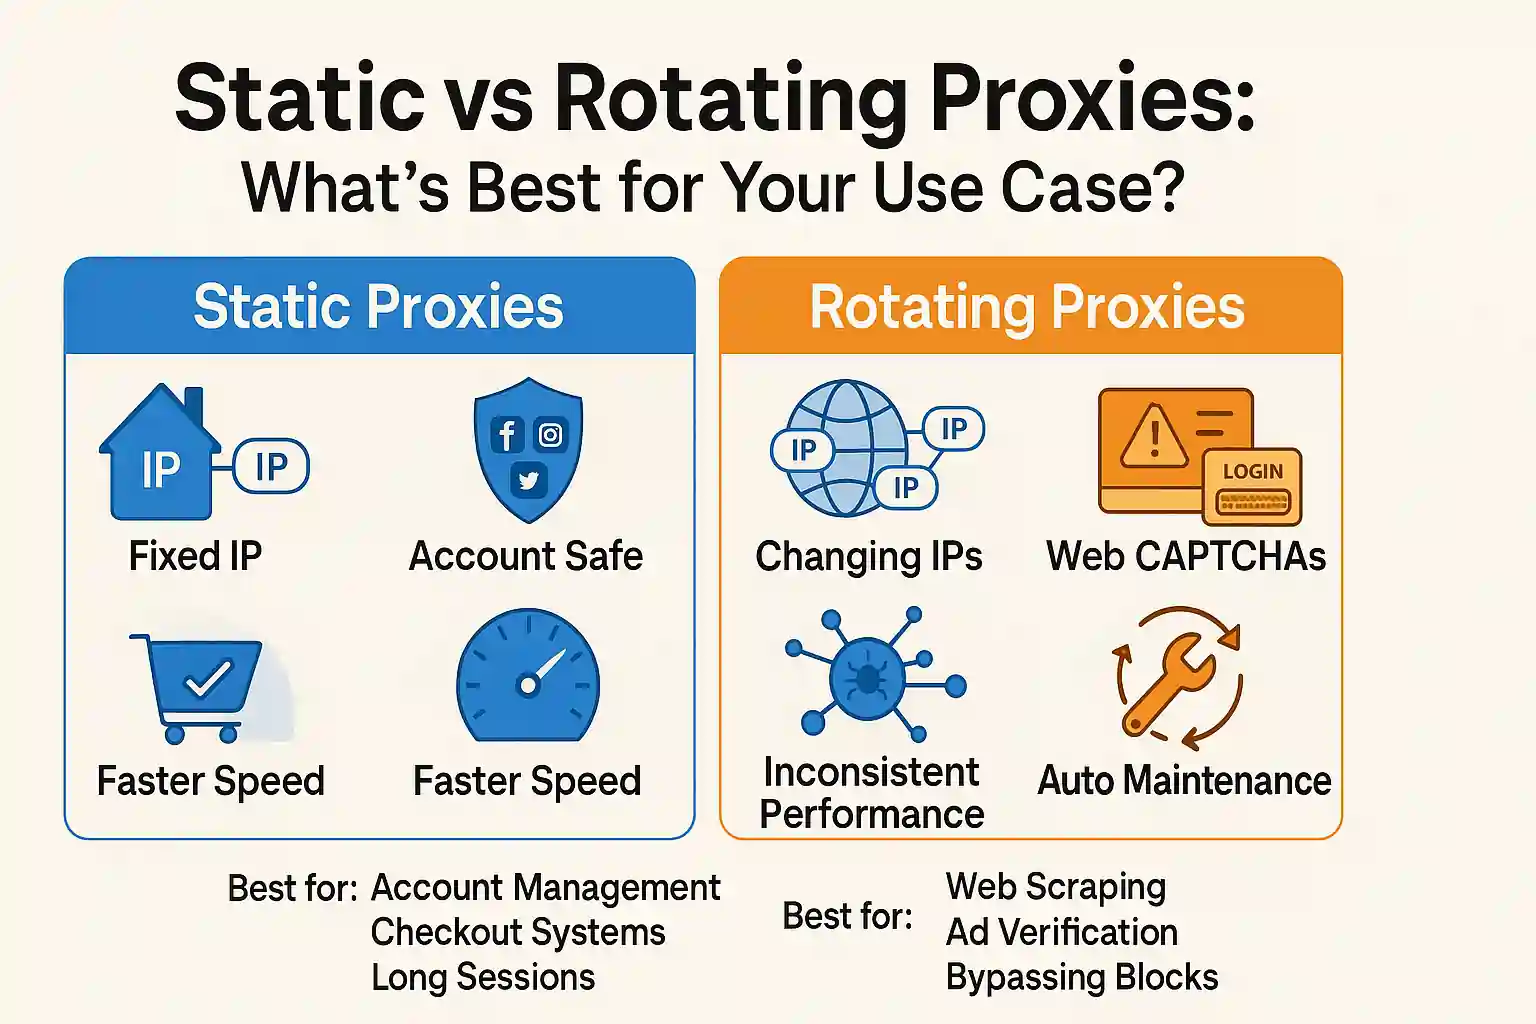
If APIs obstruct, proxies turn. Governance, observability, and elastic scaling are baked into the architecture, not bolted on after the fact. The result is resilience. Modern scraping infrastructure doesn't simply runit recovers, keeps schema, enforces access controls, and integrates cleanly into downstream systems. This is the difference between break-fix scripts and production-grade facilities.
Impacts of Automatic Proxy Nodes for Businesses
Market data shows the trend. A lot of growth projections track scraping software application. But software alone does not fix scale, compliance, or pipeline dependability. Lots of tools stop working to reflect the covert spend on internal infrastructure or outsourced information pipelines. Market leaders now purchase infrastructure, not simply tools. Straits Research study: $718.86 M in 2024 $2B by 2033 (13.29% CAGR) Research Nester: $703.56 M in 2024 $3.52 B by 2037 (13.2% CAGR) Mordor Intelligence: $1.03 B in 2025 $2B by 2030 (14.2% CAGR) These figures include business tools, managed services, and platform-scale builds.
This focus on durability has led numerous companies to transition from internal scripts to handled services, viewing the procedure as a reliable instance of web scraping as a service. Scraping has moved from the developer desk to the conference room. Companies now view it as a data supply chainsomething that need to be observable, repeatable, and certified.
Modern web data scraping infrastructure is layered by design. Each layer deals with a specific functioningestion, change, governance, or deliveryand must scale separately. What follows is a practical plan of how dispersed scraping architectures must be built for resilience, reuse, and real-time operations. Without this modular structure, the infrastructure of scraping systems stops working under pressure.
Why Anonymized Tools Power Web Mining
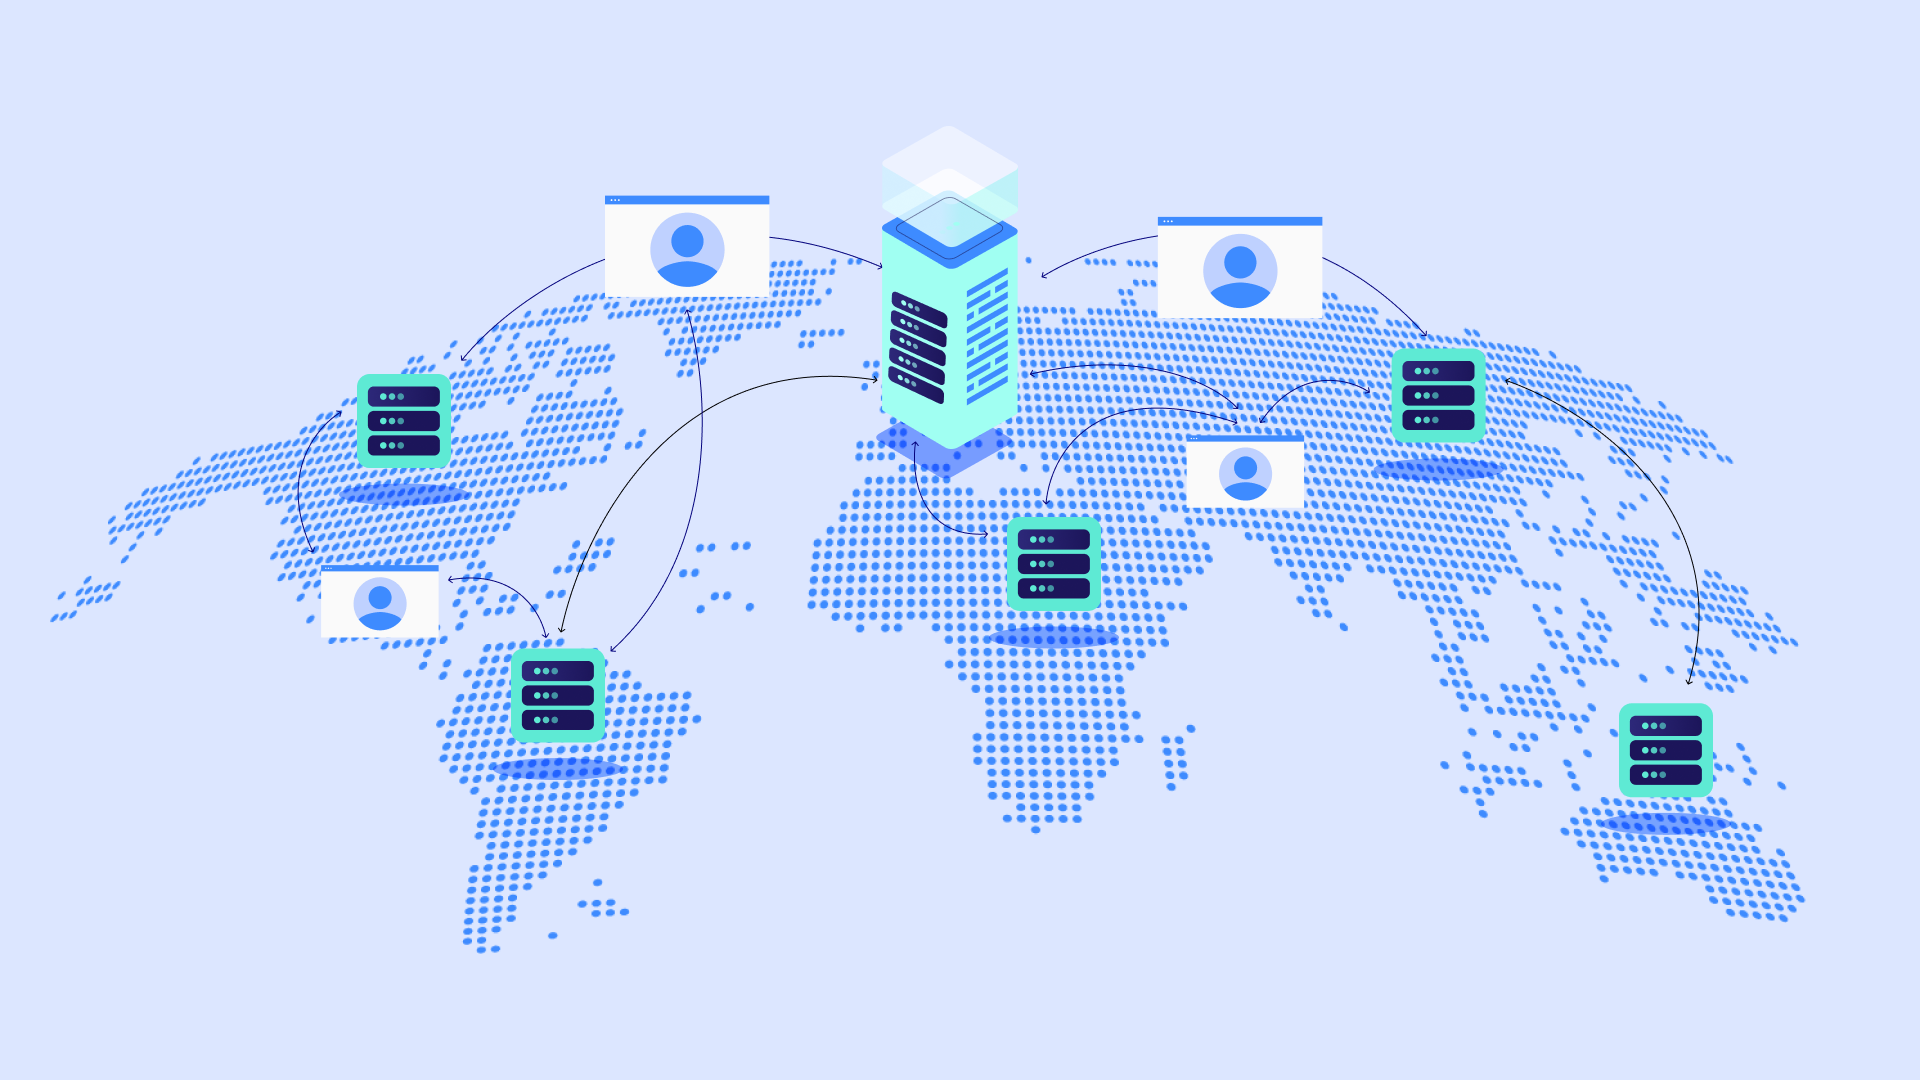
They develop crawl bottlenecks, drop tasks under load, and fail across time zones or regions. Distributed crawling usages message lines (e.g., Redis, RabbitMQ) and parallel workers to split crawl jobs throughout nodes: Jobs are designated by top priority Failures are retried instantly Regions and load are balanced dynamically Scraping becomes flexible and fault-tolerant.