Comparing Internal and Rotating Proxy Setups
For any service tracking costs, stock, listings, or news throughout markets, it's the only method to stay precise and ahead in real time. Instead of breaking, a durable infrastructure of web scraping spots layout shifts and reroutes to backup parsers automatically. It flags inconsistencies and brings in brand-new guidelines without stopping the pipeline.
The result: continuous data circulation. Structured scraping systems provide tidy, identified, and licensed data tagged by product, region, and usage rights.
Developing a powerful and scalable web scraping infrastructure needs a sophisticated system and precise planning. Initially, you require to get a team of experienced developers, then you require to establish the facilities. Finally, you require a strenuous round of testing before you are excellent to start information extraction. One of the most difficult parts stays the scraping facilities.
Today we will be discussing some vital components of a robust and well-planned web scraping infrastructure. When scraping websites, specifically wholesale, you require some sort of automated scripts (generally called spiders) that need to be set up. These spiders ought to be able to produce numerous threads and act separately so that they can crawl multiple web pages at a time.
Maximizing Extraction Rates With Rotating Nodes
State you want to crawl information from an e-commerce site called Now let's state Zuba has multiple subcategories such as books, clothing, watches, and smart phones. As soon as you reach the root website, (which can be ), you would like to create 4 different spiders (one for webpages starting with, one for those beginning with and so on).
They may multiply more in case there are subcategories under each category. These spiders can crawl information separately and in case among them crashes due to an uncaught exception, you can resume it individually without interrupting all the other ones. The creation of spiders would likewise help you to crawl information at set time periods so that your data is always revitalized.
Web scraping does not imply "event and discarding" of information. You must have validations and checks in place to make certain that dirty data does not wind up in your datasets rendering them ineffective. In case you are scraping data to fill particular data-points, you should be having constraints for each information point.
all inclusive GSA SER VPSHow Residential Tools Power Digital Mining
For names, you can check if they consist of several words and are separated by spaces. In this way, you can make sure that filthy or corrupt information do not creep into your data-columns. Before you tackle finalizing your web scraping structure, you must put in significant research to inspect which one supplies the optimum data precision because that will lead to better results and less need for manual intervention in the long run.
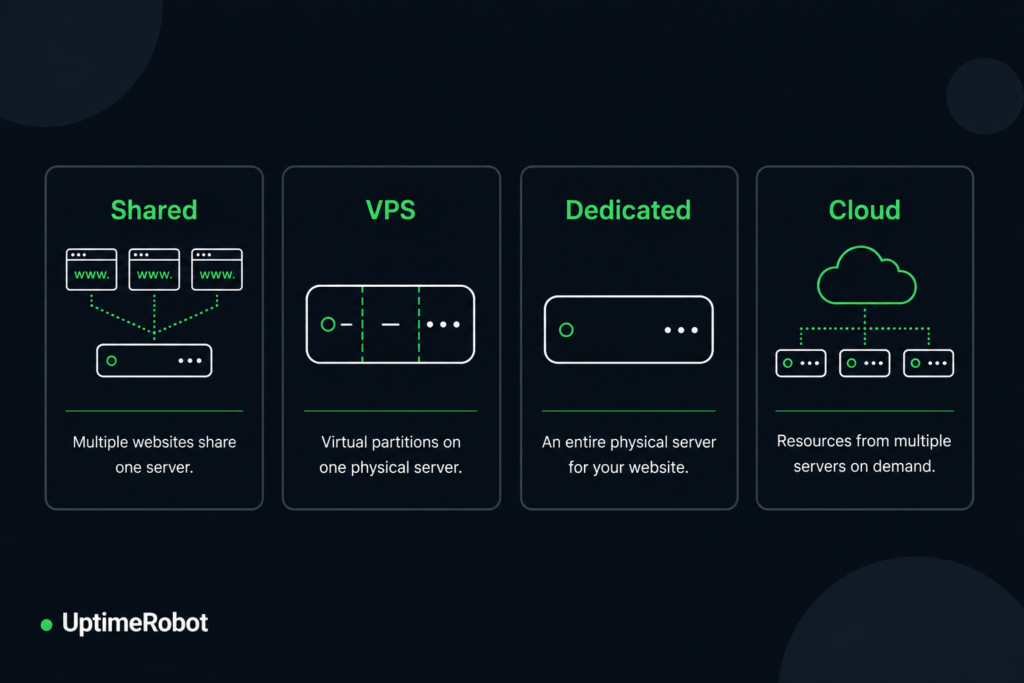
When we talk about running spiders and automated scripts, we normally imply that the code would be deployed in a cloud-based server. It helps you run code on a Linux or a Windows server which is handled and preserved by their team at AWS.
You are charged just for the uptime and you can stop your server in case you plan not to utilize it for a long time. Setting up your scraping facilities on the cloud can prove to be really cheap and reliable in the long run, however you will need cloud designers to set things up and look after upgrading them or making modifications to them as and when required.
Designing Future-Proof Internal Proxy Networks
, which is the cheapest data-storage solution on the market today. There are more expensive solutions that you can choose depending on how regularly you desire to access the data.
When scraping a single web page, you can run the script from your laptop and finish the job. In case you are attempting to crawl data from thousands of web-pages of a single site every second, you will be blacklisted and blocked from the website in less than minutes.
When we talk about running spiders and automated scripts, we generally mean that the code would be released in a cloud-based server. Among the most frequently utilized and cheap options is AWS-EC2 by Amazon. It assists you run code on a Linux or a Windows server which is managed and preserved by their team at AWS.
Configuring Low-Cost Backconnect Nodes for 2026
You are charged just for the uptime and you can stop your server in case you prepare not to utilize it for a long time. Establishing your scraping facilities on the cloud can show to be very inexpensive and efficient in the long run, however you will require cloud designers to set things up and take care of upgrading them or making modifications to them as and when needed.
, which is the least expensive data-storage service on the market today. There are more pricey solutions that you can choose depending on how frequently you want to access the data.
When scraping a single web page, you can run the script from your laptop and do the job. However in case you are trying to crawl data from thousands of web-pages of a single website every 2nd, you will be blacklisted and blocked from the site in less than minutes.