Architecting Future-Proof Local IP Infrastructures
; HttpRequest demand = HttpRequest.newBuilder(). POST(HttpRequest.
BodyHandlers.ofString()); (()); using var client = new HttpClient(); client.; var response = await customer. PostAsJsonAsync( "", payload ); var material = wait for reaction.
A lot of web scraping projects begin with a script. Someone writes a few lines of code, runs it against a website, and data appears in a file or database. The information updates.
In truth, that script is just solving the tiniest part of the problem. It shows you can extract information once. It does not prove you can do it reliably, safely, and continually. At a small scale, that distinction does not matter. At a big scale, it matters a lot. When scraping a couple of pages, working implies the script runs without errors.
At scale, working suggests the information is right today, tomorrow, and next month. It suggests groups rely on the output enough to make choices with it. Scripts are not developed for this meaning of working.
Optimizing High-Bandwidth Crawling Infrastructure in 2026
Parsing is not what breaks scraping systems in production. What breaks systems are layout modifications, partial failures, rate limits, obstructing, retries, and quiet data shifts.
At scale, parsing is perhaps 10 percent of the work. The other ninety percent is everything around it. The most unsafe scraping failures are the ones you do not see. A selector still returns a value, but it is the wrong worth. A product page loads, however the primary content is changed by an approval message.
In all of these cases, the script keeps running. Infrastructure can identify these patterns. Scripts can not, unless you keep adding delicate checks that ultimately become uncontrollable.
Modern Anonymized Web Harvesting Techniques and Stacks
They alter whenever the website owner desires. At scale, you are not scraping one website. You are scraping lots of throughout areas, categories, and formats.
Scripts typically assume the world remains the exact same. The web never does. Modern sites seldom obstruct based upon code alone. They look at habits patterns. They enjoy demand timing, frequency, headers, navigation flow, and session habits. If your traffic looks abnormal, you get throttled, challenged, or served alternate material. Managing this is not about composing smarter parsing code.
These are infrastructure problems. A script can send out demands. Facilities controls how those requests act with time. When scraping becomes essential to the company, reliability expectations rise. People anticipate the information to be there every day. They anticipate gaps to be described. They expect failures to be handled without manual intervention.
Infrastructure permits you to specify expectations and keep an eye on variances. Scripts typically simply collect whatever comes back. At scale, scraping raises questions beyond engineering.
Comparing Dedicated and Residential Proxy Solutions
This ends up being especially crucial when scraped data feeds AI systems. As soon as data influences models, traceability matters. Could you please let me know which source failed, when it failed, and how much information is impacted?
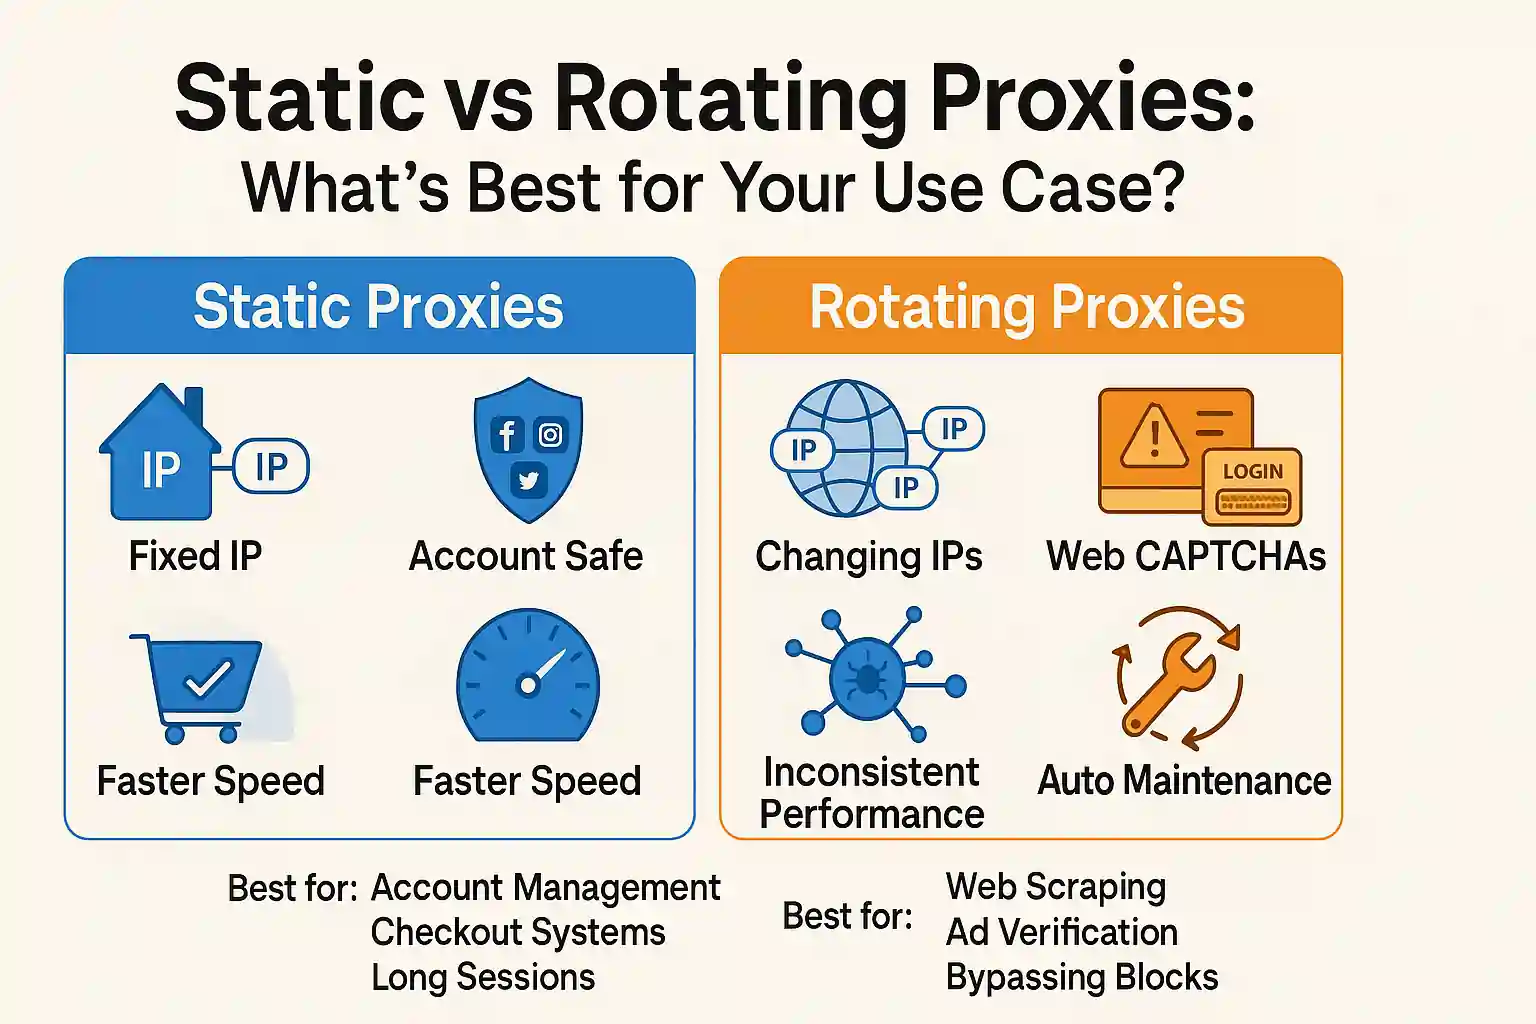
shared vs private proxiesMany groups do not prevent facilities because they are reckless. They avoid it due to the fact that scripts feel faster. Facilities feels heavy and sluggish at the beginning.
At scale, scraping facilities usually consists of central scheduling, source-aware crawling, rate and habits control, proxy and identity management, validation layers, tracking, signaling, family tree tracking, and healing workflows. Scripts still exist inside this setup.
Ways to Set Up High-Performance Internal Proxy Servers
The objective is to stop depending upon them alone. Web scraping is no longer a side job. It feeds pricing systems, market analysis, forecasting, and AI training. When scraping stops working, genuine decisions are impacted. As the value of web information boosts, so does the cost of getting it wrong. Facilities decreases that risk.
It is about constructing systems that make it through modification. Scripts can begin the journey. Infrastructure is what makes it reputable. Teams that understand this early build information pipelines they can trust. Groups that do not typically discover it later on, when the expense is much greater. Cheers, guys, see you next time.
Web scraping infrastructure has changed manual scripts as the structure of scalable huge data operations. Companies that as soon as relied on easy page parsers now need full systems that draw out, structure, and provide information in real timeacross geographies, platforms, and compliance borders. Legacy scraping toolslike standard spiders and fixed selectorsfail under pressure.
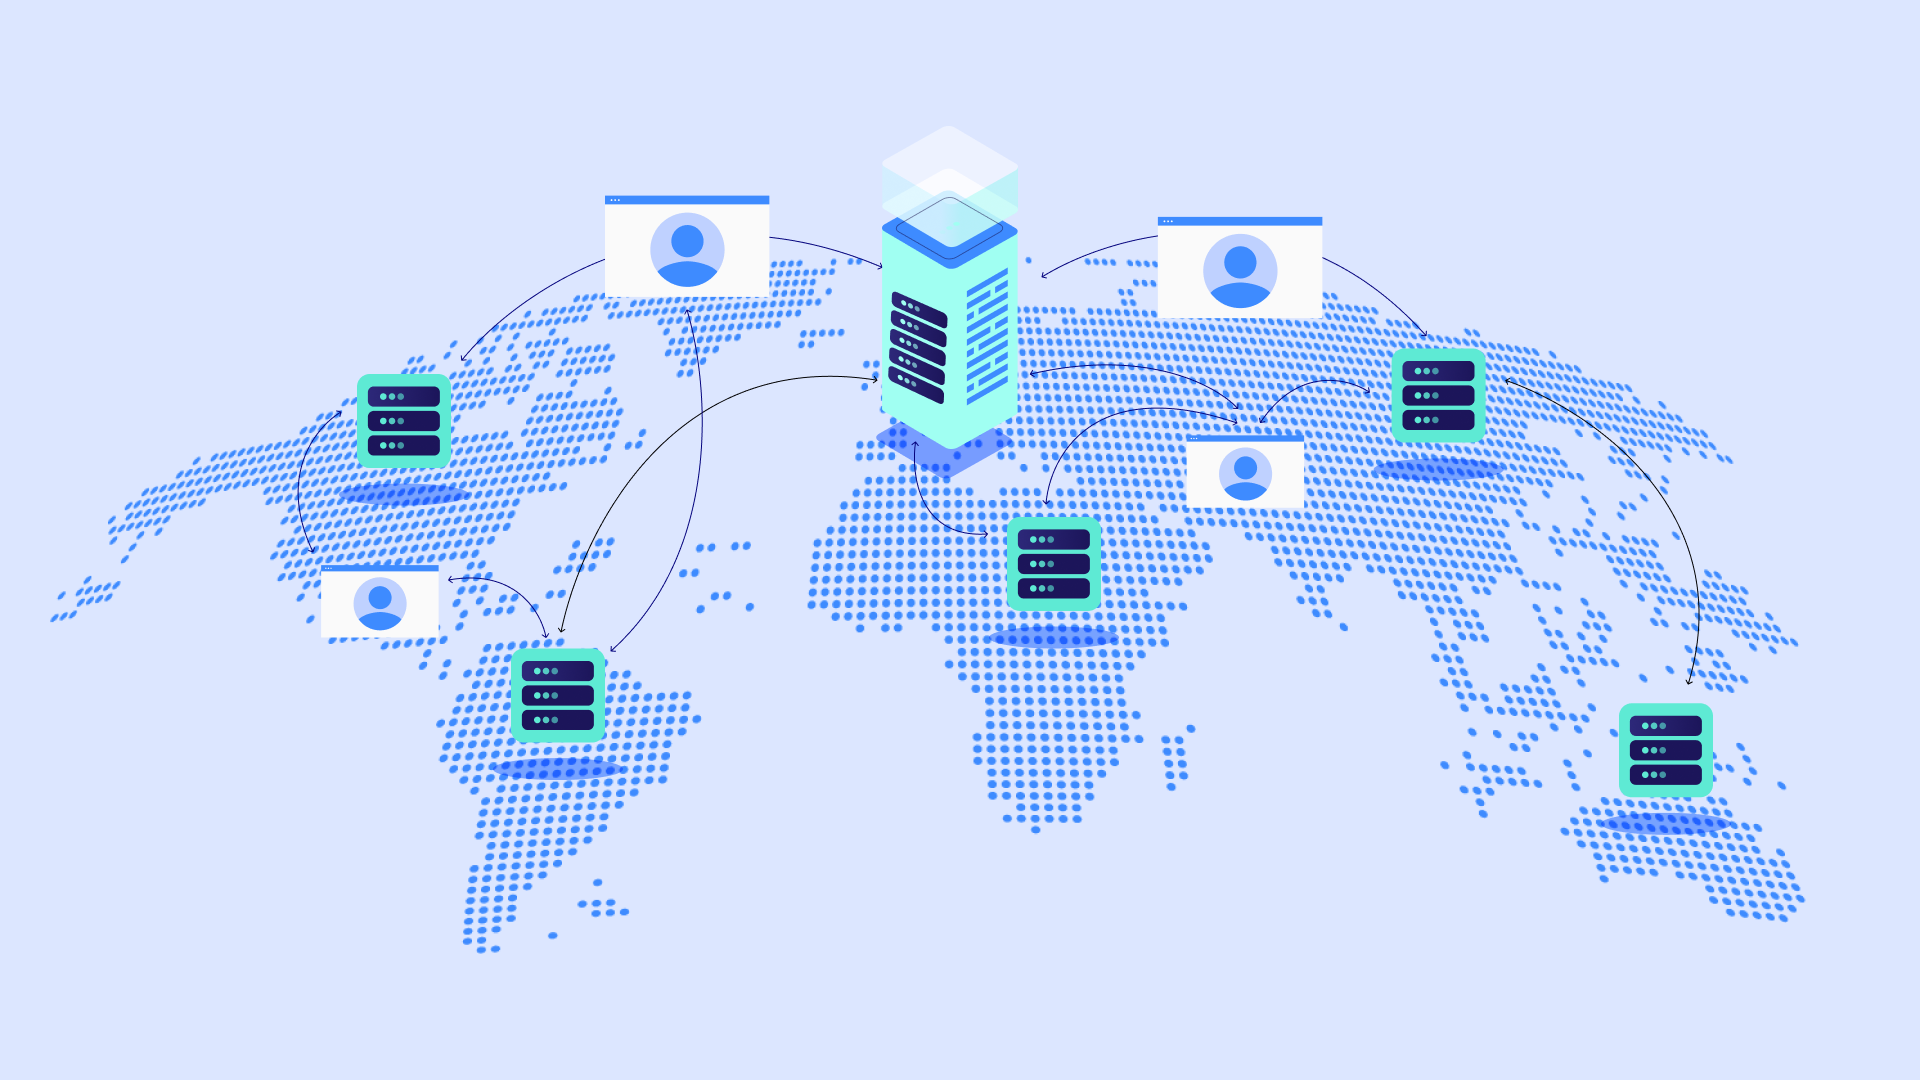
Most notably, they can't meet enterprise needs: No fault tolerance No schema enforcement No shipment guarantees Distributed web scraping systems are built for scale. They divided the scraping pipeline into clear layerscrawling, queuing, changing, and deliveringand scale each one separately. These systems adapt dynamically: If a node fails, traffic reroutes.
If APIs obstruct, proxies turn. Governance, observability, and flexible scaling are baked into the architecture, not bolted on after the fact. The outcome is strength. Modern scraping infrastructure doesn't simply runit recovers, preserves schema, enforces gain access to controls, and incorporates cleanly into downstream systems. This is the distinction in between break-fix scripts and production-grade facilities.
Setting Up Low-Cost Residential Proxies for 2026
Market information shows the trend. Most growth projections track scraping software application. Lots of tools fail to show the covert invest on internal infrastructure or outsourced information pipelines.
This focus on resilience has actually led numerous firms to shift from internal scripts to managed services, viewing the procedure as a trusted instance of web scraping as a service. Scraping has moved from the developer desk to the boardroom. Companies now view it as an information supply chainsomething that need to be observable, repeatable, and compliant.
Modern web information scraping infrastructure is layered by style. Each layer handles a particular functioningestion, improvement, governance, or deliveryand needs to scale individually. What follows is a practical blueprint of how distributed scraping architectures need to be developed for resilience, reuse, and real-time operations. Without this modular structure, the infrastructure of scraping systems stops working under pressure.
Modern Private Information Harvesting Tools and Systems
They develop crawl bottlenecks, drop tasks under load, and stop working across time zones or regions. Dispersed crawling usages message lines (e.g., Redis, RabbitMQ) and parallel workers to split crawl jobs across nodes: Jobs are designated by concern Failures are retried instantly Regions and load are balanced dynamically Scraping becomes flexible and fault-tolerant.